Context: In a standard transformer, generating token t requires comparing it against the stored key and value vectors of every previous token. That store is the KV cache; it grows linearly with context length and, at 100k+ token contexts, it dominates GPU memory and bandwidth. Linear attention is the family of alternatives that compress all history into a fixed-size state instead — trading exact recall for constant memory.
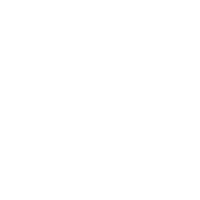
Linear attention. Delete the softmax from attention and you can reassociate the matrix products, turning cost from quadratic to linear in sequence length. Concretely, all history collapses into one d×d matrix S, updated as S_t = S_{t-1} + v_t k_tᵀ, with output o_t = q_tᵀ S_t. Softmax attention must touch every past key and value; this touches only S.
The useful reframing: treat S as an associative memory mapping keys to values, and read the update as one step of gradient descent on the loss −⟨S k_t, v_t⟩. Each token is a tiny online-learning step improving retrieval.
DeltaNet fixes the obvious problem — that loss is unbounded below, so S grows without limit and old and new information smear together. Replace the objective with ½‖S k_t − v_t‖² and the update becomes the delta rule:
S_t = S_{t-1} − β_t (S_{t-1}k_t − v_t) k_tᵀ
The term S_{t-1}k_t − v_t is the stale association for this key, so the update surgically erases the old value before writing the new one, rather than piling on top of it.
Gated DeltaNet adds an LSTM-style forget gate α multiplying S, giving the model control over memory lifespan. KDA promotes α from a scalar to a diagonal matrix, so each channel of the state decays at its own learned rate. That per-channel decay doubles as positional information — which is why K3 can drop rotary position embeddings from its full-attention layers entirely and let KDA carry position.
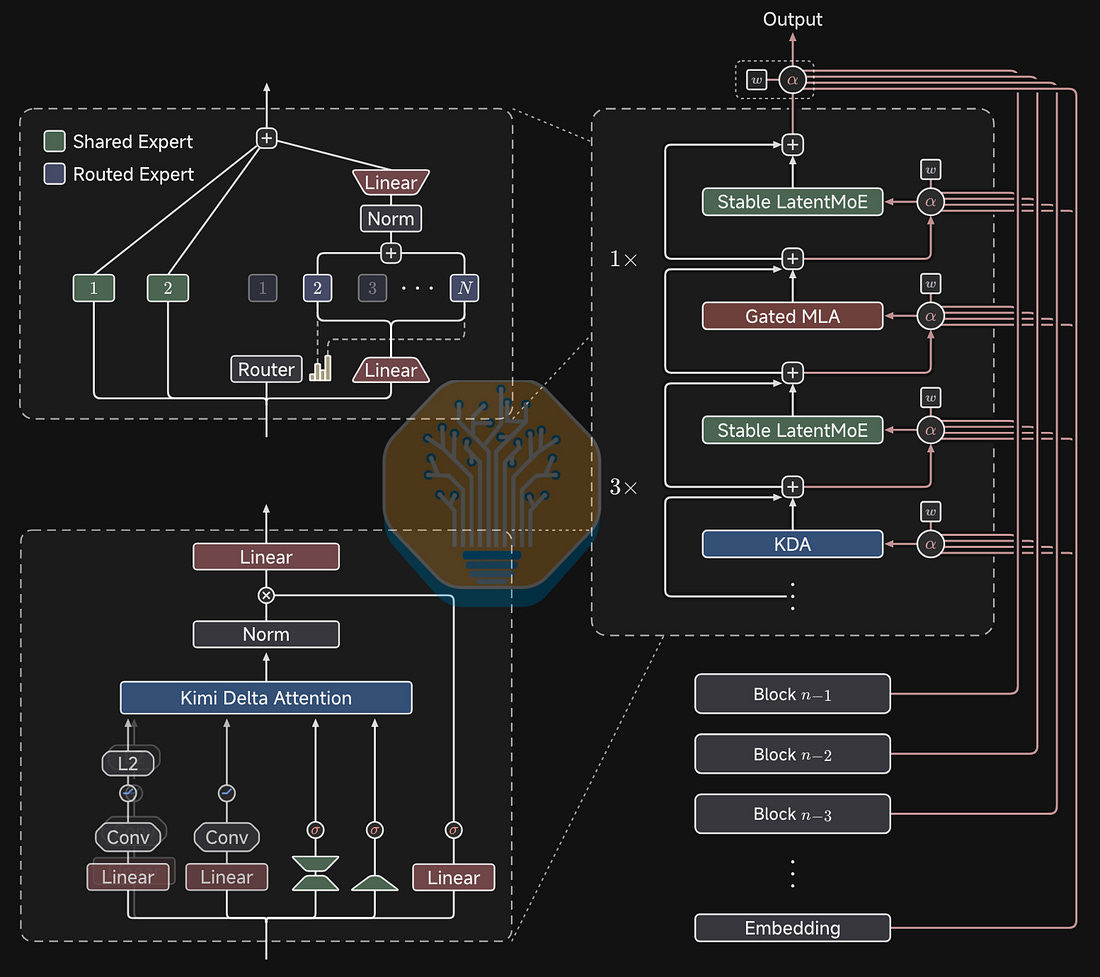
Around the core recurrence, KDA applies a short causal (left-padded) convolution to queries, keys and values to capture local dependencies, and L2-normalizes queries and keys to keep the state-transition matrix's spectrum stable. Output is normalized per head, passed through an output forget gate, then mixed across heads with a linear layer.
Moonshot open-sourced FlashKDA. Decode follows the recurrence directly. Prefill can't — a token-by-token recurrence wastes a GPU's matrix-multiply hardware — so the recurrence is unrolled in chunks of C tokens and rewritten in matrix form, with cumulative decay factors folded into modified Q and K matrices and a lower-triangular mask enforcing causality. Two kernels: one precomputes the chunk-level tensors (including a matrix inverse done via a truncated Neumann series, i.e. six chunk-sized matmuls), one runs the chunk-to-chunk recurrence.
The cost accounting is the point:
Context: An arithmetic intensity of ~7/8 FLOP per byte is absurdly low — modern accelerators need hundreds of FLOPs per byte to stay compute-bound. So KDA decode is purely bandwidth-limited. The win isn't efficiency per operation; it's that the thing being read is a small fixed-size state rather than a KV cache that grows to gigabytes at long context.
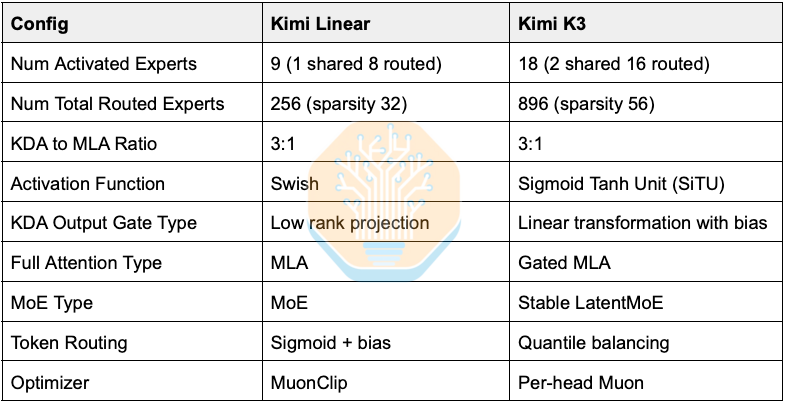
Kimi Linear was Moonshot's proof-of-concept for KDA, so it's the best guide to K3's architecture. The shared-expert count, the 3:1 KDA-to-full-attention ratio, and the general attention module design carried over. What changed: roughly double the active experts (18 vs 9), a much larger and sparser expert pool (896 routed experts vs 256), a new activation function, a gated variant of full attention, "Stable LatentMoE," quantile-based routing, and a per-head version of the Muon optimizer.
The MLA question. K3's full-attention layers use Multi-head Latent Attention — DeepSeek's scheme that compresses keys and values into a low-rank latent vector, shrinking the KV cache.
Context: MLA's "absorption trick" folds the up-projection matrices into the query and output projections, so at decode time you only read the small latent instead of reconstructing full keys and values. The cost is extra FLOPs during prefill. That's a good trade when you're generating lots of tokens per prompt (reasoning), and a bad one when you're processing enormous prompts and emitting a few tokens (agentic tool use).
SemiAnalysis flags this as K3's odd choice: every other frontier open model — GLM 5.2, DeepSeek V4, MiniMax M3, MiMo V3 — has moved to sparse-attention schemes built on Grouped Query Attention (multiple query heads sharing one KV head), precisely because agentic workloads are prefill-dominant. They expect Kimi K4 to replace MLA. This is their speculation, not reporting.
Their argument: KV cache size in isolation tells you little. Nobody ships static cache-compression schemes; how much memory is left over for cache depends on the parallelism strategy (wide expert parallelism vs tensor parallelism leaves very different footprints); and architecture efficiency changes how fast you fill the cache in the first place.
Their proposed metric is KV throughput = KV cache size ÷ time-to-first-token, at a given sequence length.
Context: This is the minimum interconnect bandwidth you need for prefill/decode disaggregation — the now-standard practice of running prompt processing on one pool of GPUs and token generation on another. The prefill pool has to physically ship the KV cache to the decode pool, and it has to do so as fast as prefill produces it. Hence bytes ÷ prefill time.
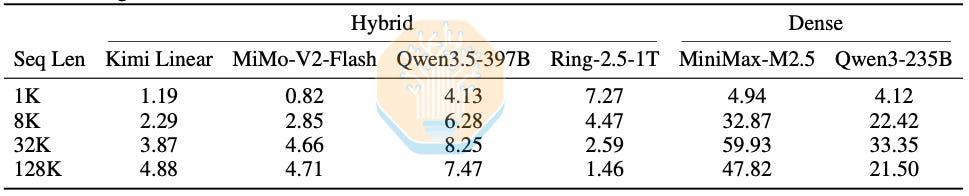
They benchmark this across hybrid-attention models (Kimi Linear, MiMo-V2-Flash, Qwen3.5-397B, Ring-2.5-1T) and conventional dense-attention ones (MiniMax-M2.5, Qwen3-235B) from 1K to 128K tokens, and argue the hybrid advantage widens with context length.
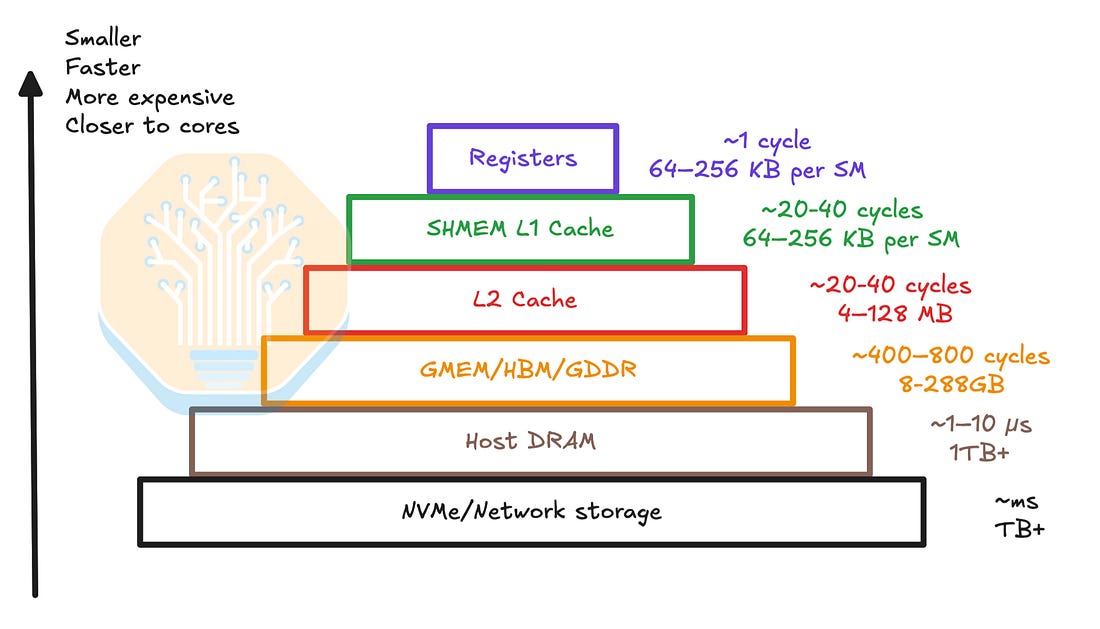
Where the cache lives. Same hierarchy as any computer: HBM on the GPU first (whatever capacity model weights and activations leave behind), spilling to host DRAM, then to SSD. The Mooncake Store framework treats this as a genuine cache-coherence problem, supporting write-through and write-back policies into a cluster-wide distributed cache pool — which buys cross-node prefix sharing, deduplication of the KV cache across tensor-parallel MLA ranks, and redundancy when a node dies.
The prefix-cache catch. Inference engines get most of their savings from prefix caching: if a new request shares its opening tokens with a cached one, skip recomputing them. This works because standard attention stores a per-token entry you can truncate anywhere. KDA doesn't — it has one running state, and to allow a cut at an arbitrary position you'd have to snapshot the state at every token, which puts memory growth right back where it was. Moonshot's answer is coarse snapshots: vLLM saves KDA state every 32K tokens, plus at prompt boundaries (in agentic loops, a new turn almost always begins at the end of a prompt).
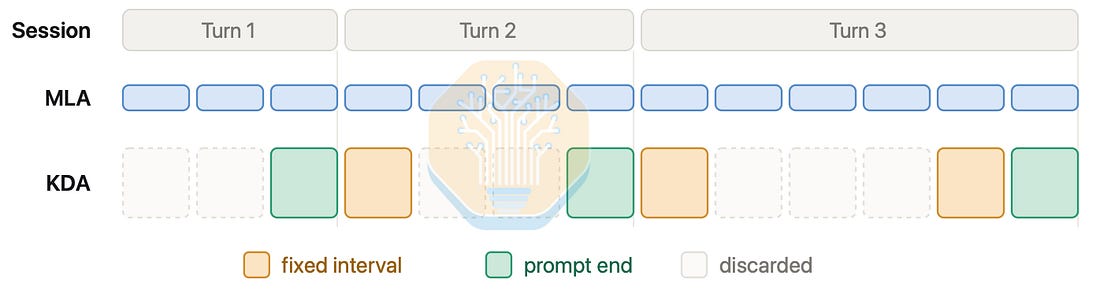
So: KDA cuts cache memory a lot, but in production it does not consume a constant amount.
Standard residual connections (x_{l+1} = x_l + f(x_l)) are what made deep networks trainable — they give features a path from shallow to deep layers and gradients a path back without vanishing. But the residual stream is a single shared bus: early layers dominate it, information is irreversibly overwritten as depth grows, later layers compensate by increasing their output gain (destabilizing training), and no layer has selective access to any particular earlier layer's output.
Moonshot's fix borrows from sequence modeling: recurrent networks had the same dilution problem along the time axis, and attention solved it by letting any position retrieve any earlier position. Attention Residuals run softmax attention along the depth axis. Each layer attends over the representations produced by all previous layers. The query is not derived from the input — it's a learned parameter per layer.
The problem is communication: on a model sharded across many GPUs, attending over all L previous layer outputs costs O(L·d) traffic. Block Attention Residuals partition L layers into N blocks; a layer attends over the completed blocks' aggregate outputs plus the running partial sum within its own block, cutting communication to O(N·d) with, they report, minimal quality loss.
Reported results: 1.25× compute efficiency versus standard residuals, consistently lower validation loss with the gap widening during the learning-rate decay phase, bounded output magnitude with depth (instead of the usual growth), and stable gradient magnitudes.
Training. Attention Residuals break pipeline parallelism, because layer group N needs the outputs of all N−1 earlier groups.
Context: Pipeline parallelism splits a model's layers across GPUs and streams micro-batches through, like an assembly line. Modern schedulers give each physical GPU several non-contiguous layer chunks ("virtual stages") to reduce idle bubbles. Attention Residuals mean every stage needs data from every earlier stage — naively, quadratic communication in the number of stages.
The fix is cross-stage caching: the first virtual stage pays the full transfer cost and each rank stores the completed block representations locally; every subsequent virtual stage reuses the cached copies and transfers only what it lacks. Communication drops from quadratic to linear in the number of physical stages, and the savings scale with the number of virtual stages — enough that transfers fully overlap with compute. Combined with activation checkpointing (which eliminates the intra-block intermediate tensors), memory cost matches the standard architecture and total training overhead is ~4%.
Inference splits into two phases mirroring prefill and decode: one batched pass computing attention against all completed blocks simultaneously (returning softmax statistics for reuse), then a sequential online-softmax update against the evolving current block — FlashAttention's trick applied along depth. Net I/O ends up close to a standard residual network.
Context: In a mixture-of-experts layer, each token is routed to a handful of expert feed-forward networks out of hundreds. With expert parallelism, experts live on different GPUs, so every token's activation vector must be sent across the network to its experts and the results sent back. This all-to-all communication is the dominant scaling headache in MoE training and inference.
LatentMoE compresses the token vector before dispatch and decompresses after the results come back. K3's "Stable" variant adds an RMSNorm before the up-projection to reduce scale sensitivity.
Communication volume is proportional to (tokens × active experts × expert input dimension) and inversely proportional to the expert-parallel size. That explains K3's configuration cleanly: Kimi K2 used 8 active experts at input dimension 7168; K3 halves the dimension to 3584, which buys a doubling to 16 active experts at identical communication volume.
But SemiAnalysis argues the more decision-relevant quantity is the ratio of communication time to compute time, since that sets the ceiling on how much of the all-to-all can be hidden behind expert math. Working it through for a SwiGLU expert (6·d·m FLOPs per token):
T_comm / T_comp = (P·F) / (6·m·B) · (1 − 1/E)
where P is bytes communicated per activation element, F is per-GPU expert compute throughput, B is per-GPU network bandwidth, m is the expert intermediate dimension and E the expert-parallel size. Note what dropped out: the expert input dimension, the active expert count, the token count. The only architectural knob is m. Widen the expert's hidden layer and a larger fraction of communication becomes hideable.
That, they argue, is why K3 (and DeepSeek V4 Pro, MiniMax M3, MiMo V2.5 Pro, Inkling) all pushed expert intermediate dimension up to ~3072: as hardware compute throughput rises and expert weights are stored in ever-lower precision, F grows and the ratio worsens unless m grows with it.
Quantile balancing. MoE routers need load balancing or a few experts get swamped. The current standard (DeepSeek's auxiliary-loss-free method) nudges per-expert router biases by a small tuned coefficient each step. Quantile Balancing, from a Feb 2026 blog post by Jianlin Su, instead solves for the bias that would have balanced the current batch and applies it to the next — no hyperparameter. Each token's cutoff is its (k+1)-th highest biased router score; for each expert you sort the margins between its score and every token's cutoff, and set the bias so exactly q = mk/n margins sit above threshold. Since q/m = k/n, that threshold is the (1−k/n) quantile — hence the name. Updates shrink to nothing automatically once load is balanced.
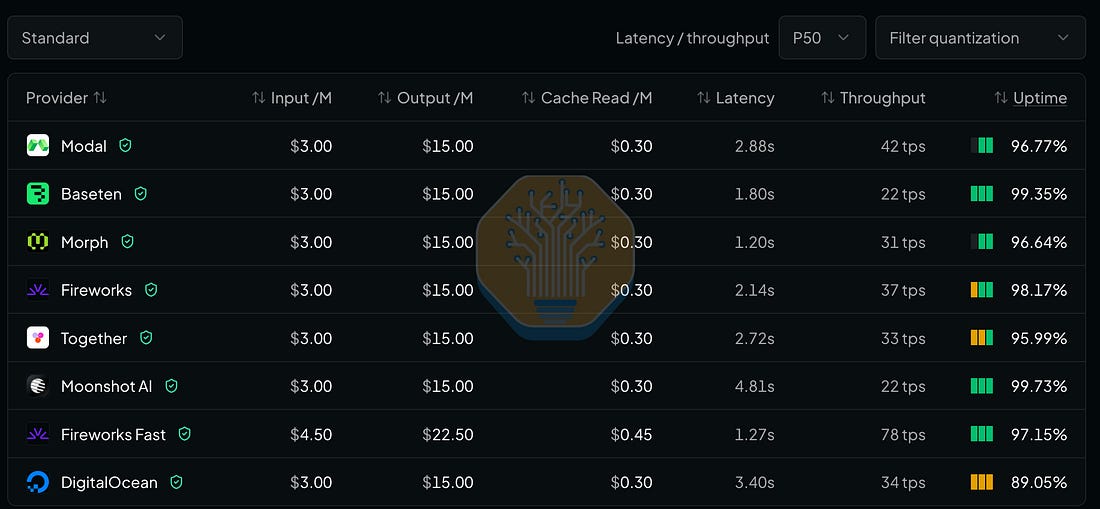
As of July 30, every provider on OpenRouter prices K3 at a floor of $3 per million input tokens and $15 per million output. Both Nvidia and AMD had day-zero vLLM recipes with DRAM offload and speculative decoding; bring-up was easier than DeepSeek V4 because Moonshot shipped documentation, container images and a speculative-decoder draft model simultaneously with the weights.
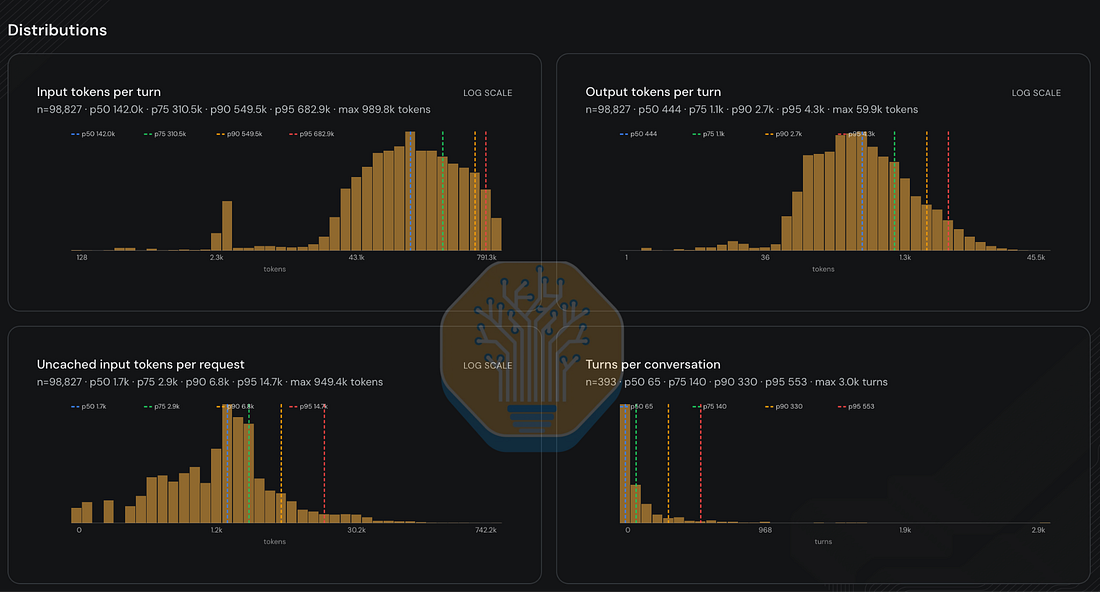
SemiAnalysis benchmarks on replayed real Claude Code traces rather than synthetic prompt/response lengths: median 142K input tokens, median 444 output tokens per turn, median 65 turns per session. The lopsided ratio is characteristic of agentic harnesses, where nearly every action — including file edits — is a tool call.
The hardware finding is the interesting one:
Context: That last number is the practical takeaway. At 95% prefix-cache hit rate, an agentic turn re-reads almost nothing; at under 10%, you recompute 142K tokens of prompt every turn. The difference is an order of magnitude in cost per session. So the binding constraint on serving K3 economically is not FLOPs or even weights — it's leftover HBM capacity for cache, which is why one generation of memory capacity (B200 → B300) changes the whole deployment picture.
Kimi K3 took the world by storm at its announcement, sweeping leaderboards and establishing itself as the open frontier model. While the community is eager to understand how Kimi K3 works, many have been surprised by the unconventional techniques driving its performance. This article serves as a primer to understanding the core techniques of the Kimi K3 model architecture.
Kimi Delta Attention (KDA) is the linear attention layer in Kimi K3’s hybrid attention mechanism. We trace the origins of KDA, starting from linear attention, DeltaNet, Gated DeltaNet (GDN), then to KDA.
The derivation of linear attention stems from removing the softmax operation in the standard softmax attention. Below we compare the iterative inference formulas, which show the computation of the output vector at token position t:
By removing the softmax operation, we can reorder the operations and reduce the computation complexity of attention from quadratic to linear:
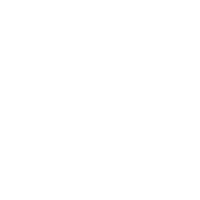
The new equations are as follows:
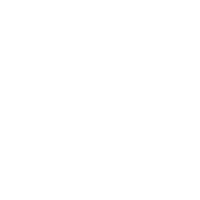
Vectors q, k, v, have dimensions L by d. The computational complexity of both equations are O(Ld²), thereby making the computation linear. Comparing the new equations with softmax attention’s equation, we see that softmax attention requires accessing all past key and value vectors, whereas linear attention compresses all past key and value vectors into one hidden state S.
We reinterpret the new equations as an online learning objective. We view matrix S as an associative memory that stores the associations between key vector k and value vector v, and we retrieve v by multiplying S with k. We can then interpret the first equation as continuously updating the matrix S at every position to perfect the retrieval. Finally, we can interpret the vt @ kt.T term as the gradient of loss function -(S @ kt.T) @ vt with respect to S.
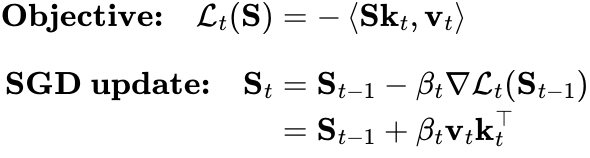
Under the online learning objective view, we see the values of matrix S will grow unboundedly: old and new information gets blurred together in S as the sequence grows, which destabilizes learning. Without softmax giving well-scaled and bounded outputs, linear attention typically lags behind softmax attention on long-range recall tasks.
DeltaNet improves upon linear attention by changing the loss function to minimizing the L2 norm of the value retrieval. Unlike linear attention’s loss function, DeltaNet’s loss function regularizes the growth of S. This creates a new matrix S update rule, the Delta Rule, as below:
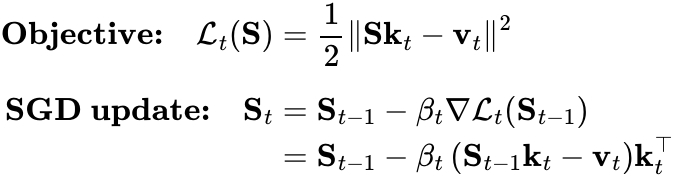
Source: Linear Attention and Beyond (Interactive Tutorial with Songlin Yang)
The Delta Rule becomes the basis of DeltaNet’s attention equation:
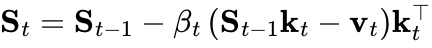
Conceptually, Sₜ-1 @ kₜ - vₜ represents the associations irrelevant to the current key and value, and DeltaNet performs targeted removal of those associations.
GDN and KDA are adaptations of DeltaNet. Gated DeltaNet applies the LSTM forget gate alpha on the matrix S, allowing the model to control memory lifespan with weight decay. KDA further expands alpha into a diagonal matrix that enables fine-grained per-channel memory decay and positional awareness.
%250A%255Cmathbf%257Bk%257D_t%255E%255Ctop%250A%255C%255C%255B8pt%255D%250A%255Cmathbf%257BS%257D_t%255E%257B%255Cmathrm%257BKDA%257D%257D%250A%2526%253D%250A%255Cstyle%257Bcolor%253Ared%257D%257B%255Coperatorname%257BDiag%257D(%255Calpha_t)%257D%250A%255Cmathbf%257BS%257D_%257Bt-1%257D%250A-%250A%255Cbeta_t%250A%255Cleft(%250A%255Cstyle%257Bcolor%253Ared%257D%257B%255Coperatorname%257BDiag%257D(%255Calpha_t)%257D%250A%255Cmathbf%257BS%257D_%257Bt-1%257D%255Cmathbf%257Bk%257D_t%250A-%250A%255Cmathbf%257Bv%257D_t%250A%255Cright)%250A%255Cmathbf%257Bk%257D_t%255E%255Ctop%250A%255Cend%257Baligned%257D%26version%3D9)
Thanks for reading SemiAnalysis! This post is public so feel free to share it.
Moonshot developed FlashKDA, their custom kernels for KDA, and open-sourced it. Here we explain the algorithm and derive the arithmetic intensity.
First, let’s start from an alternative formulation of the recurrence formula:
u_t = beta_t * (v_t - (D_t @ S_t-1).T @ k_t)
S_t = D_t @ S_t-1 + k_t @ u_t.T
o_t.T = q_t.T @ S_t
Here, D_t is the diagonal matrix of the alpha forget gate, and u_t is the delta in the delta rule. For decode, the kernel roughly follows the formula. For prefill, we parallelize the operation by unrolling the recurrence formula in chunks of tokens, in order to efficiently execute the operations on GPUs. Assume we unroll token i to j, and the starting state is S_i-1, we get:
S_j = D_j:i @ S_i-1 + sum(D_j:t+1 @ k_t @ u_t.T, t=i:j)
o_j.T = q_j.T @ S_j
      = q_j.T @ D_j:i @ S_i-1 + sum(q_j.T @ D_j:t+1 @ k_t @ u_t.T, t=i:j)
D_j:i refers to the cumulative decay from token i to j: D_j @ D_j-1 @ D_j-2 @ … @ D_i. In FlashKDA’s matrix form, the formula becomes:
S_out = D_j:i @ S_in + K_restore.T @ U
M_qk = tril(Q_decay @ K_inv.T)
O = Q_decay @ S_in + M_qk @ U
The vector to matrix mapping is as follows:
S_in refers to the state at the starting position of a chunk
S_out refers to the state at the end position of a chunk
K_restore is the matrix form of D_j:t+1 @ k_t
Q_decay is the matrix form of q_j.T @ D_j:i
Q_decay @ K_inv.T the matrix form of q_j.T @ D_j:t+1 @ k_t, derived from (q_j.T @ D_j:i) @ (D_t:i^-1 @ k_t)
M_qk is the causal mask, so it’s a lower triangular matrix
U is the matrix form of unrolled u_t. To compute this, we apply UT transform and compute the following:
B = Diag(beta) @ (V - K_decay @ S_in)
L = StrictTril(Diag(beta) @ K_decay @ K_inv.T)
U = (I + L)^-1 @ B
Please consult Songlin Yang’s blog post and Kimi Linear paper section 3.1 for the full derivation. Note that here U corresponds to the pseudo-value term in the Kimi Linear paper.
Implementation-wise, FlashKDA launches 2 kernels: K1 and K2. K1 prepares chunk-level tensors in parallel, including:
a = exp2(cumsum(g))
K_decay = Diag(a) @ K
Q_decay = Diag(a) @ Q
K_inv = Diag(a)^-1 @ K
K_restore = a[-1] * K_inv
L = StrictTril(Diag(beta) @ K_decay @ K_inv.T); INV = (I + L)^-1
M_qk = tril(Q_decay @ K_inv.T)
Here a is the cumulative decay, where each element is the cumulative decay at a token position.
K2 performs chunk-level recurrent computation:
U = INV @ Diag(beta) @ (V - K_decay @ S)
O = Q_decay @ S + M_qk @ U
S = Diag(a[-1]) @ S + K_restore.T @ UHere we analyze the complexity of an attention head. For decode, the critical path computations are:
D_t @ S_t-1: Element-wise multiplication, D × D
S_t-1.T @ k_t: D × D × 1
k_t @ u_t.T: D × 1 × D
q_t.T @ S_t: 1 D × D
The decode kernel roughly performs 7*D² FLOPs.
Reading and writing the FP32 recurrent state dominates the memory traffic, so the memory traffic is roughly 8*D² bytes.
For prefill, the critical path of K1 is at computing L, INV, and M_qk.
L: C × D × C
INV: Neumann factorization, performs 6 C × C × C matrix multiplications
M_qk: C × D × C
For K2,
K_decay @ S: C × D × D
Q_decay @ S: C × D × D
M_qk @ U: C × C × D
INV @ B: C × C × D
K_restore.T @ U: D × C × D
Combining K1 and K2, FlashKDA performs 12*C^3 + 8*C²*D + 6*C*D² FLOPs. Since we analyzed at the chunk level (chunk size C), assuming sequence length T >> C, the overall FLOPs is T/C * O(C*D²) = O(T*D²).
For memory traffic:
K1 read Q, K, g: C × D
K1 write and K2 read Q_decay, K_decay, K_restore: C × D
K1 write and K2 read INV, M_qk: C × C
K2 read V and write O: C × D
K2 read and write S once per kernel: D × D
In total, FlashKDA accesses 3 * 2*C*D + 2 * (3 * 2*C*D + 2 * 2*C*C) + 2 * 2*C*D = 8*C² + 22*C*D bytes. At the kernel level, it accesses T/C * (8*C² + 22*C*D) + 8*D² ~ O(TC + TD + D²).
This concretely shows that the computational complexity of KDA:
Prefill: Linear to sequence length for both computation and memory
Decode: Constant to sequence length for both computation and memory
Moonshot trained Kimi Linear models as proof of concept for their KDA design, so we can infer Kimi K3’s architecture design from Kimi Linear. Comparing the K3 release tech blog with Kimi Linear, we see Kimi K3 shares the shared expert count, the hybrid linear attention ratio, and the general attention module design.
The diagram above shows the operations performed on the inputs of KDA. For the query, key, and value, we apply linear transformation and short convolution. Applying short convolution effectively capturing local token dependencies, and doing a left padding convolution avoids breaking causality. We additionally apply L2 norm to the query and key to stabilize the eigenvector of the transition and the output matrices. For the decay memory gates, alpha is a low rank projection, and beta is a down projection. The KDA output is normalized per head and controlled by an output forget gate, implemented as a linear transformation in K3, instead of a low rank projection in Kimi Linear. Finally, we apply a linear layer to mix per-head information.
Kimi Linear interleaves KDA with full attention Multi-head Latent Attention (MLA). Kimi Linear showed that 3:1 is the ideal KDA to MLA ratio that balances performance and efficiency. KDA also serves as a strong position-aware operator, replacing the RoPE in MLA.
Keeping MLA as full attention is an interesting choice, as all other open weight models move to Grouped Query Attention (GQA). MLA uses an absorption trick to reduce the computation of a decode step at the cost of extra computation during the prefill step. This is a sensible trade-off for decode-dominant reasoning workloads, but for prefill-dominant agentic workloads, extra computation becomes a high cost with little benefits. As a result, all frontier open weight models use GQA-based attention mechanisms: GLM 5.2 DeepSeek Sparse Attention, DeepSeek V4 Compressed Sparse Attention, MiniMax M3 MiniMax Sparse Attention, and MiMo V3 HySparse are all based on GQA. We suspect Moonshot’s future models such as Kimi K4 will feature attention mechanisms that replace MLA.
We argue that one should not infer KV cache efficiency solely based on KV cache space complexity. KV cache size is not a standalone factor but a property of the model design: no open weight models are released with static KV cache compression techniques, and model architecture inference efficiency affects KV cache efficiency. The effects of KV cache size also vary, depending on the total memory capacity of a deployed model instance. For example, deploying a model with wide expert parallelism has very different memory profiles than doing so with tensor parallelism, which affects the memory capacity left for KV cache. Thus, we propose considering both the model architecture system efficiency and the KV cache size to understand the KV cache efficiency, and we quantify that with KV throughput.
KV throughput is defined as KV cache size divided by the prefill time (Time to first token), given a specific sequence length. KV throughput represents the minimum bandwidth required to reliably serve a model with PD disaggregation, but it is also a good proxy for understanding KV cache efficiency. Prefill time encapsulates the efficiency of the model architecture, and as the sequence length increases, we will see the memory-bounded and the compute-bounded situations. As shown in the table below, we can see the benefits of hybrid linear attention become more pronounced as sequence length increases.
This is also a good way to understand the bandwidth requirements of KV cache offloading to different memory tiers in a cluster.
The location where KV cache is stored follows the memory hierarchy. First, KV cache resides in HBM, the fastest memory in a GPU cluster, consuming whatever capacity is left by model weights and activations. As KV cache size exceeds the HBM capacity, it spills into server DRAM, a higher capacity but lower bandwidth memory pool. Finally, when KV cache exceeds DRAM capacity, it spills to disk storage such as SSD. This is analogous to the computer architecture cache hierarchy: register, cache memory, main memory, disk storage.
The analogy continues for memory coherency. Popular distributed KV cache framework Mooncake Store supports write-through and write-back policies for KV cache loading. Mooncake Store features a distributed KV cache pool that makes all KV cache visible to all workers. Implementing write-through policy between DRAM and the lower-level distributed KV cache pool offers multiple benefits in multi-node scenarios, including sharing prefix cache across nodes, avoid KV cache duplication for tensor parallelized MLA, and KV cache redundancy when a node goes down.
At each token position in a request, Kimi K3 KDA’s recurrent state is fixed in size, whereas standard attention KV cache grows with sequence length. This KV cache space reduction comes at the cost of complicating prefix caching, especially when Kimi K3 is a hybrid attention of KDA and MLA.
Roughly speaking, modern inference engines identify prefix cache hits by matching the longest token prefix in the existing cache.
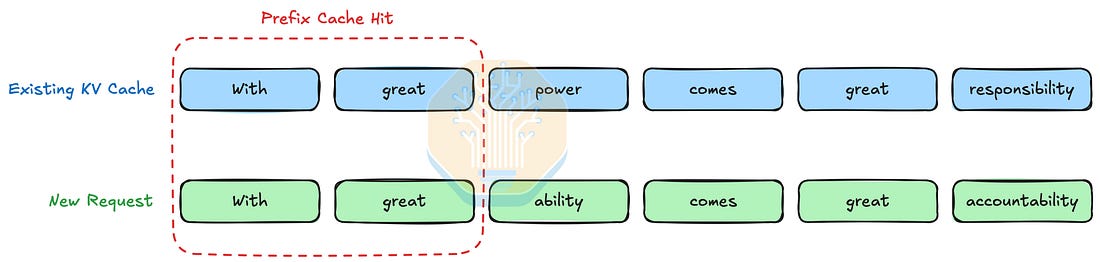
Identifying the longest prefix becomes a problem for linear attentions like KDA. Without prior knowledge of where the boundary of a prefix is, we will have to cache KDA’s recurrent state at every token position. This means every token has a cache, and the KV cache memory usage regresses to growing with sequence length, defeating the purpose of using linear attention. To tackle this problem, Moonshot saves recurrent states at a coarse granularity, e.g. vLLM caches every 32K tokens. vLLM additionally caches at prompt boundaries, since for agentic workloads, a new turn typically starts at the end of a prompt.
This shows that even though linear attentions like KDA greatly reduce KV cache memory consumption, realistically during serving, they do not consume a constant amount of KV cache memory.
Residual connections are one of the key innovations that allowed us to build bigger deep neural networks through scaling model depth. The deeper the neural network, the more expressive they become but training them naively is hard. Signals from the earlier layer need to be preserved till the last layer and gradient need to survive from output to first without vanishing.
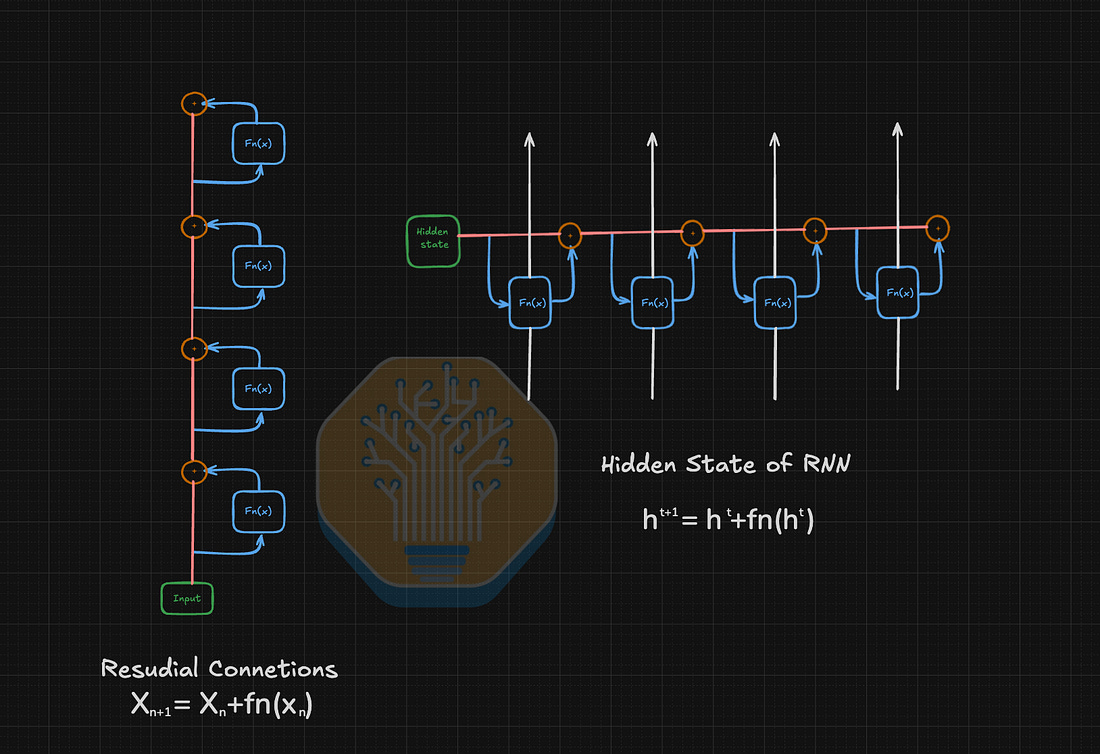
Instead of modeling whole networks as a single function, passing information only through nonlinear transformations, residual networks connect smaller blocks with identity paths. Each block fᵢ learns a change to its input xᵢ, given by the recurrence:
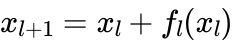
The identity mapping allows features to carry from shallower units to any deeper unit and gives the gradient a path highway so they do not vanish.
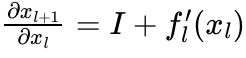
While residual connections allow us to build deeper networks, they come with challenges.
Early layers heavily influence residual stream to have effect on final output. Because of which residual stream has irreversible information loss with increasing depth. Later layers increase output gain to have effect on this modified residual stream which can destabilize training. Another variant like highway networks allow gating mechanisms for information flow but they suffer from the same crucial problem. Layers don’t have selective access to information from earlier layers.
Sequence modeling dominated by recurrent neural networks had the same recurrence formulation.
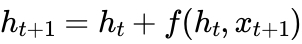
Where each step has identity mapping with previous state for direct information flow and the sequence model faced the same challenge: depth in the time axis dilutes signal.
Attention machines transformer removed this constrained by retrieving any token in past with powerful and expensive attention mechanism
Motivated by attention mechanism in sequence modeling, kimi developed attention residual, where they take attention over depth blocks,
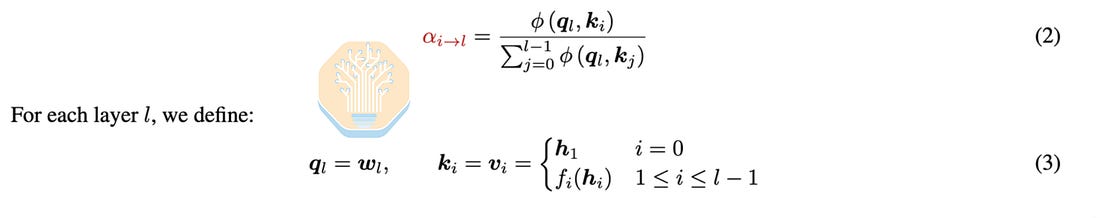
Standard causal self-attention computes the output of token $t$ as a weighted sum of previous token representations:
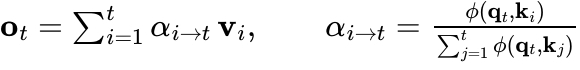
Attention Residuals use the same attention mechanism, but replace the sequence dimension with the depth dimension. Instead of attending over previous tokens, each layer attends over representations produced by previous layers.
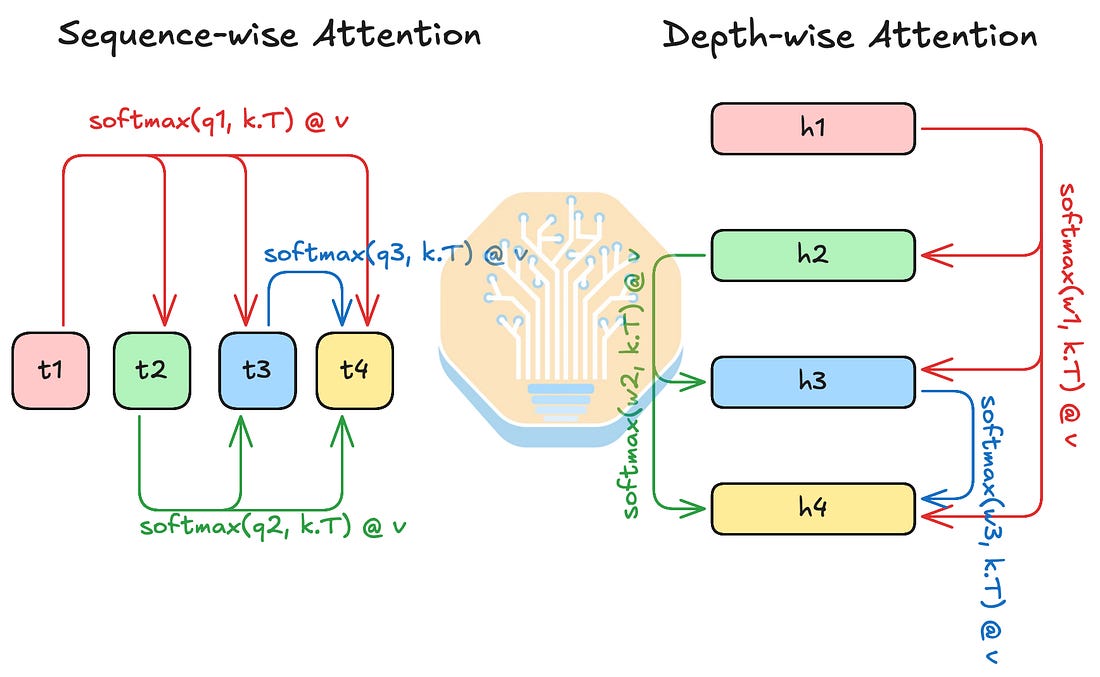
Unlike standard attention, the query is a learned parameter for each layer rather than being generated from the current token.
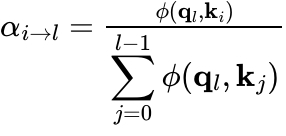
For each layer ℓ, we define:
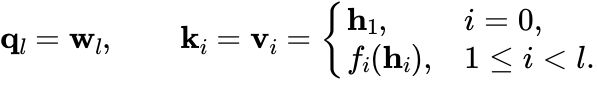
Each colored block represents the output token representation from a previous transformer layer. Just as standard causal self-attention performs softmax attention over tokens in the sequence, Attention Residuals perform softmax attention over the representations produced by previous layers.
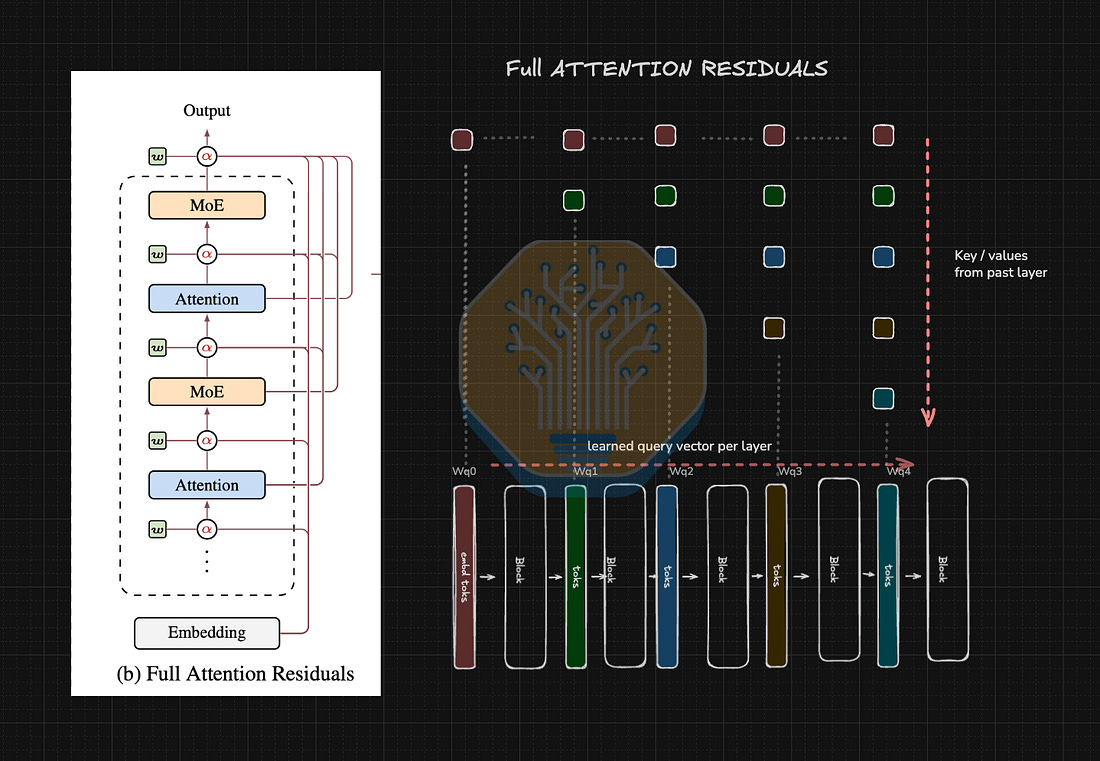
Attention residual allows the model to get fine grained control over what inputs to pick from past layers making the model more expressive.
Attention residual need to all past layer outputs for attention. For large models distributed over many GPUs this creates O(Ld) communication overhead. To overcome this block attention residual dividends layers L into N blocks of S layers. Block AttnRes applies attention over completed block outputs and for current block its evolving partial sum.
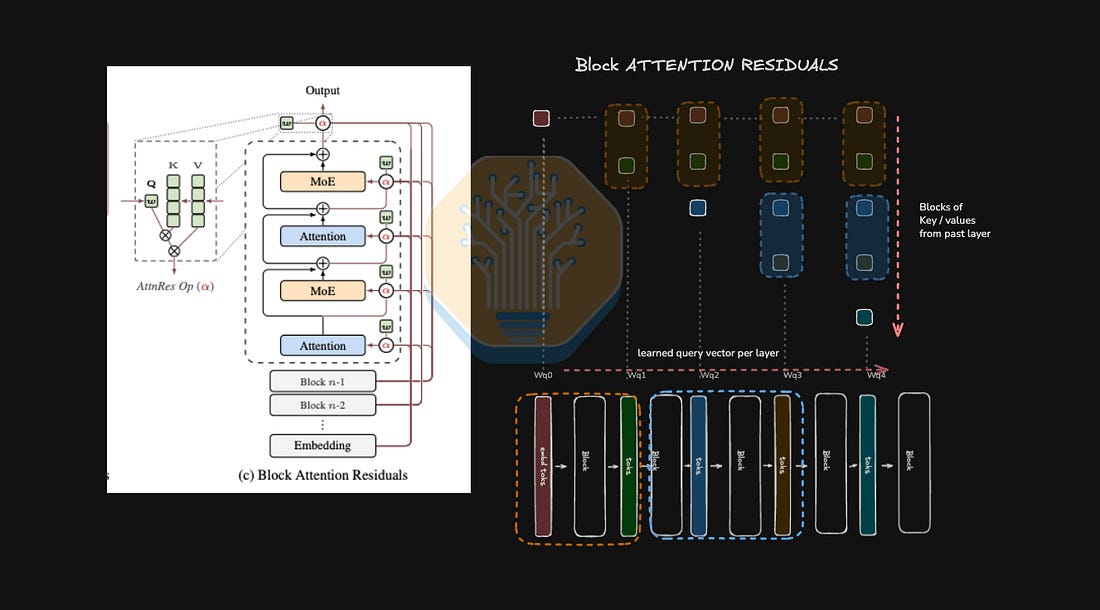
Block Attention has minimal tread over full attention residual but they cut down communication from O(Ld) to O(Nd).
Let bₙⁱ denote the partial sum over the first i layers in block n, such that
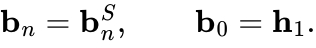
For the i-th layer in block $n$, the available block representations are
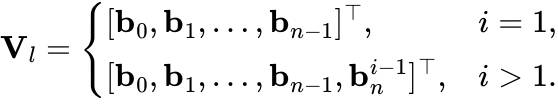
Unlike standard attention, the query is not input-dependent. Each layer learns a query vector:
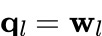
Attention weights over the available block representations are computed as
The output is the weighted sum of previous layer representations
Rather than depending only on the residual stream to preserve information, Attention Residuals give every layer direct, selective access to earlier representations. This block based variant of attention residuals greatly reduces communication overhead while having competitive performance.
Block residuals show better scaling compared standard residual connection achieving 1.25× compute efficiency. Consistently lower validation loss compared to baseline and gap widening with decay phase. Unlike standard residual networks where output magnitude increases as depth increases. selective aggregation of block attention has bounded output. And consistent gradient magnitude.
Unlike standard residual networks, attention residuals need all N-1 block input for computation of the Nth layer. This becomes a problem for pipeline parallelism as all N layer blocks output need to be transferred across stages.
With clever cross stage caching and activation checkpointing, Kimi reduced overhead to only 4% compared to standard architecture for pipeline parallelism.
For P physical stages and V virtual stages. Each block N needs C=PV communication for each chunk. Naively this needs transferring all accumulated blocks for each stage. This is quadratic cost growth for each physical and virtual stage
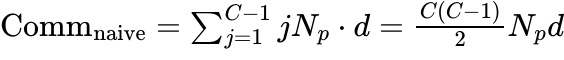
This high communication can be reduced by caching input across virtual stages. Blocks computed in earlier layer can be stored in local memory,
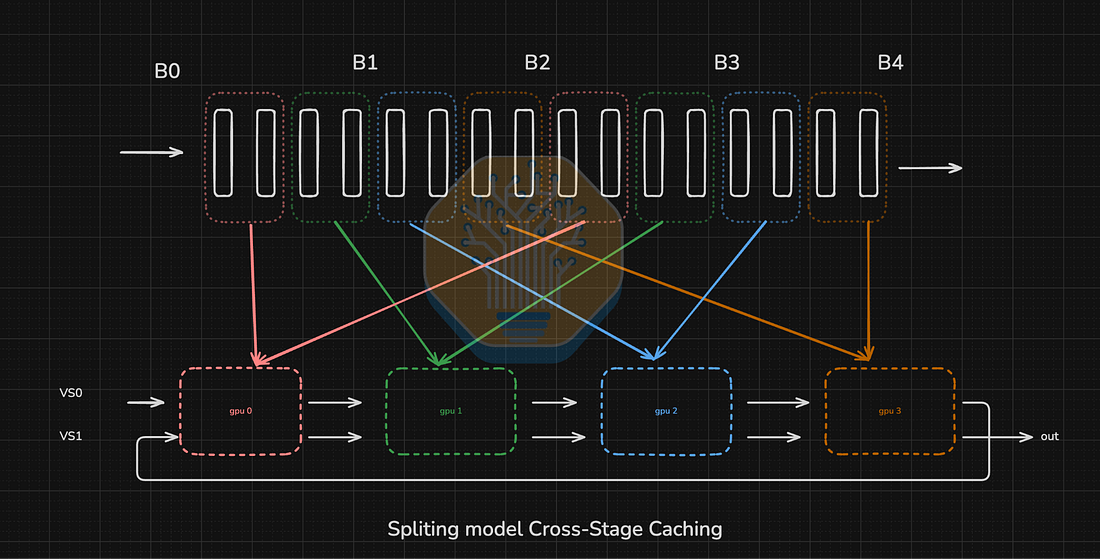
For the first virtual stage all block embedding needs to be transferred in the physical stage, each completed block is stored on respective rank. For all subsequent virtual stages all cached blocks can be reused for computation. Only the block not present on rank need to be transferred for attention to residual computation.
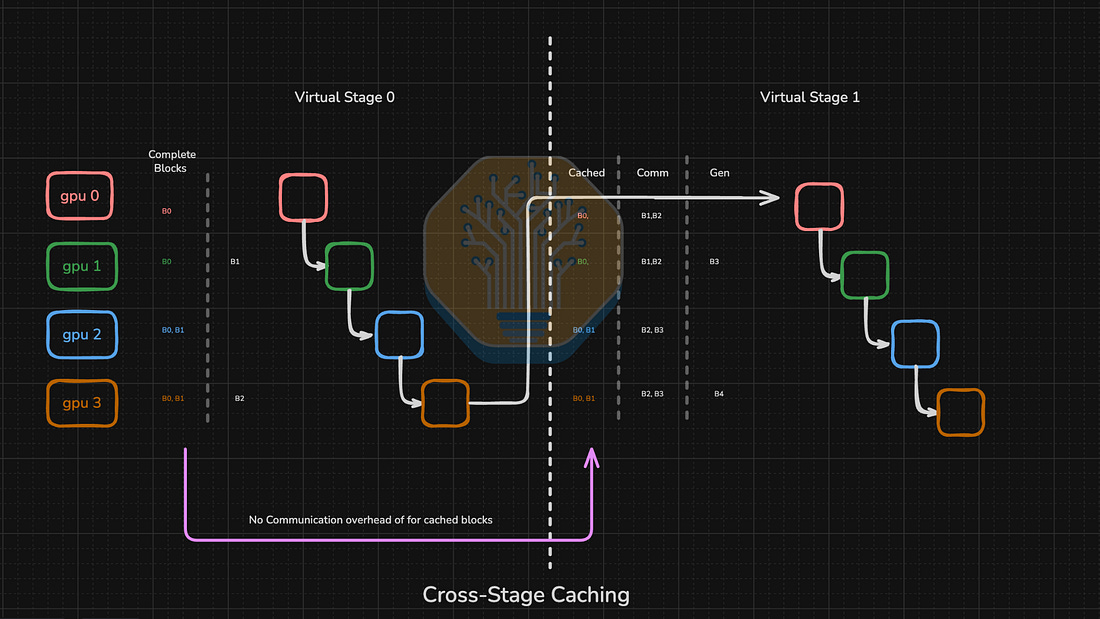
These split communication costs for first and subsequent virtual stages. For the first virtual stage its need incur the same quadratic cost for all physical layers. In subsequent virtual stages we need cached inputs from local devices and Transfer of only PNp chunks needed cutting down total communication from O(C) to O(P)
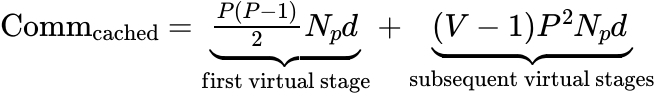
The cutdown of communication is directly proportional to virtual stages V. Because of this for full stage of one forward and backward pass all computation and communication can be overlapped
Due to cross stage caching all blocks are stored once across all V virtual stages. With Activation checkpointing all inter-block chunks for attention are eliminated. Each stage activation checkpoint Pl matches memory size of Hl of standard architecture and has no extra memory cost.
Because Attention Residuals need the output of all previous blocks to compute attention, a naive implementation has excessive memory accesses. To reduce overhead, inference is split into two phases which mirror prefill and decode stages of autoregressive attention. This computation is divided into inter-block attention for completed blocks and intra-block attention for evolving attention in the running block.
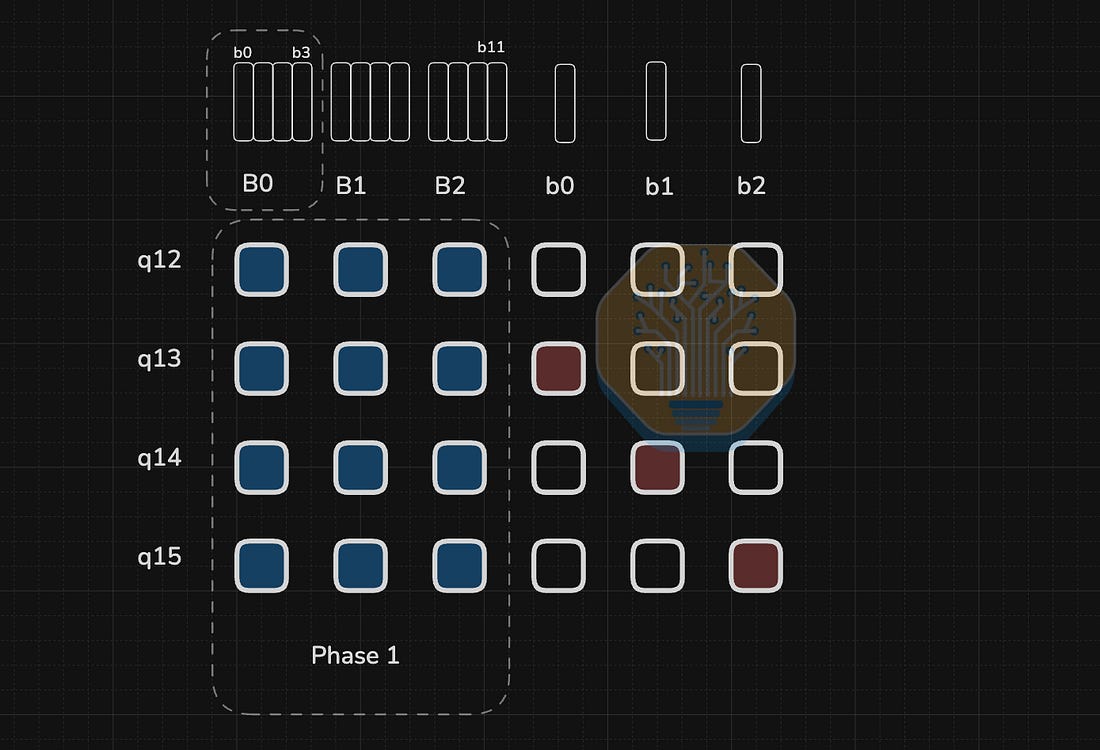
During decoding, we have to output the completed block and the query vector learned per layer. All inter block layers simultaneously with a single batched query against the completed block representations, returning both outputs and softmax statistics which can be reused for further computation. This phase is similar to prefill phase decoding
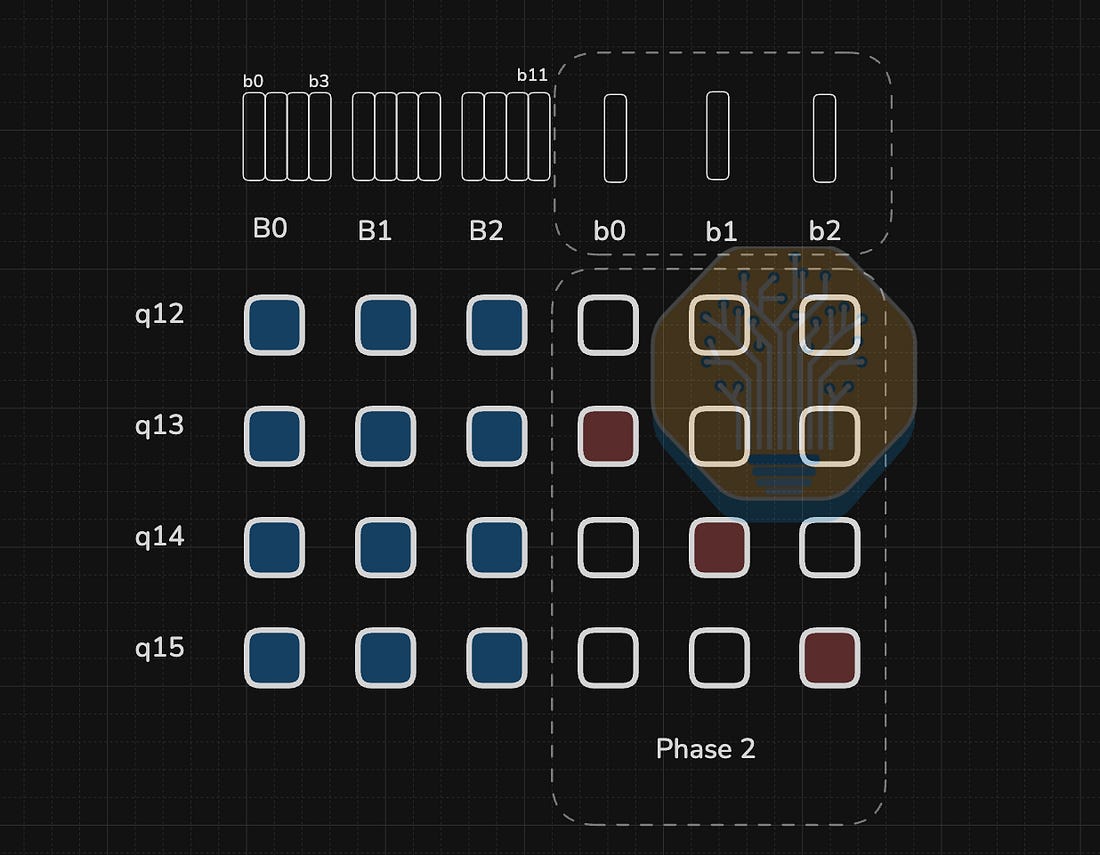
This phase is analogous to the decode phase, Similar to flash attention, evolving sum can be computed with online softmax for intra blocks combined with precomputed inter block results. Which reduces redundant memory access.
With this two phase design, the IO footprint is similar to standard residual architecture, with only the addition of phase ones inter block computation, amortized by batching all queries in the block.
LatentMoE compresses the routed tokens before the dispatch operation, and then decompresses them after the aggregation operation. In Kimi K3’s Stable LatentMoE, they apply an RMSNorm before the up-projection (decompressing) operation to reduce sensitivity to scale variations and improve model performance.
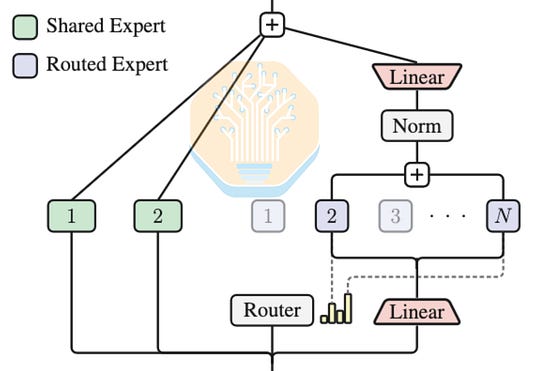
Here we explain the design principles behind LatentMoE regarding MoE communication. As shown in the LatentMoE paper, the communication volume is proportional to total routed tokens t, number of active experts K, and expert input dimension d, while being inversely proportional to the expert parallel size E. This is potentially the reason behind Kimi K3’s latent MoE dimension size and active expert count configuration. Kimi K2 series feature 8 active experts with input dimension size 7168, so Kimi K3’s latent input dimension size being 3584 (half of 7168) would allow the active expert count to double to 16 without increasing the communication volume.
However, the ratio of communication to computation time is arguably more important for estimating system efficiency (Discussions here and here). The ratio indicates the roofline of how well MoE kernels can overlap communication with computation at a throughput-bound regime, and expert intermediate dimension size is the only model configuration that affects the ratio. Specifically, increasing the expert intermediate dimension size would decrease the ratio, meaning that the theoretical maximum fraction of communication that can be hidden is higher. Here we derive the formula:
t: total input tokens across the expert parallel (EP) domain
K: number of active experts per token
N: number of total experts
E: Ranks in the EP domain
d: Expert input dimension
m: Expert intermediate dimension
P: Aggregate bytes communicated per activation element (dispatch + combine)
F: Effective FFN expert (modeled as SwiGLU) computation throughput per GPU, FLOP/s
B: Effective uni-directional network bandwidth per GPU, B/s
Assuming uniform expert routing, each GPU is assigned t * K / E tokens
Assuming uniform expert routing, an average 1 / E tokens are local to the source GPUs, so each GPU dispatches (t*K/E) * (1-1/E) tokens
Each token is a d dimensional vector, so the communication volume per token is d * P
The communication volume per GPU is (t*K/E) * (1-1/E) * d * P
The communication time T_comm = (t * K * d * P) / (E * B) * (1-1/E)
The SwiGLU computation involves 3 matrix multiplications:
Up (First) projection: d to m
Gate projection: d to m
Down (Second) projection: m to d
So the computation is 2*d*m + 2*d*m + 2*m*d = 6*d*m FLOPs per token
The computation time per GPU is T_comp = (6*d*m) * (t*K/E) / F
The communication to computation time ratio is
T_comm / T_comp
= ((t * K * d * P) / (E * B) * (1-1/E)) / ((6*d*m) * (t*K/E) / F)
= (P*F) / (6*m*B) * (1-1/E)
We believe this formula also motivates an increase in expert intermediate dimension to 3072 in not just Kimi K2 to K3, but all recent open weight models, including DeepSeek V4 Pro, MiniMax M3, MiMo V2.5 Pro, and Inkling. As hardware improves and expert weight precision reduces to save memory capacity, the compute throughput increases, so one way of reducing the ratio is by increasing the expert intermediate dimension.
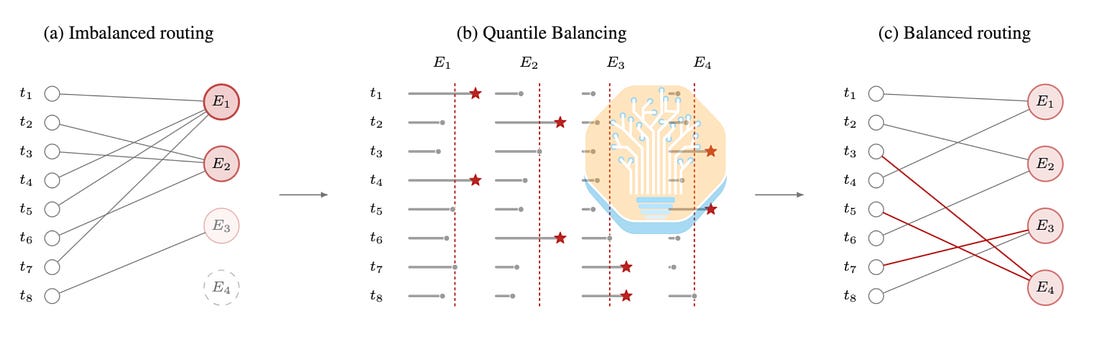
Many previous load balancing methods require careful hyperparameter tuning. Quantile balancing is hyperparameter free aux-loss free load balancing technique developed by Jianlin Su in Feb 2026 blog post
Base principle QB is the same as auxfree load balancing where router biases are updated dynamically based on the system’s load. But instead of updated bias by some small coefficient like aux-free lb, QB directly computes the next bias from the distribution of router scores relative to routing cutoff threshold. Bias updates become small naturally when the router balances load evenly.
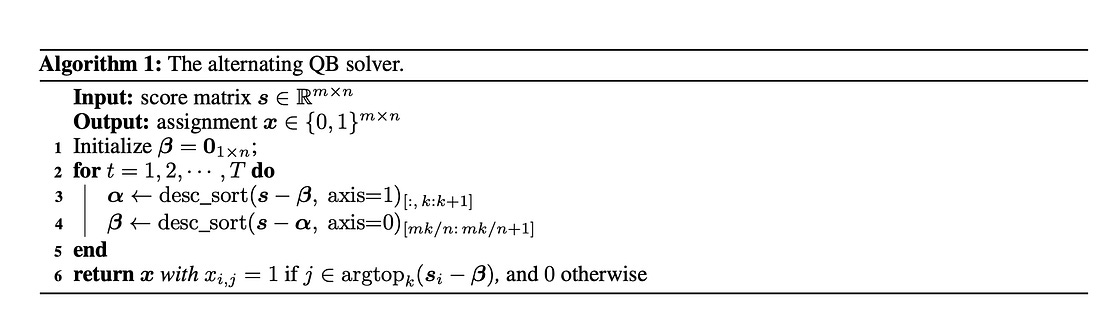
QB tries to find the bias that would have approximately balanced under the current cutoffs and routing on the current batch, solving constraint optimization problems and applying these updates for the next batch. The first constraint is that each token is routed to exactly k experts. The second constraint is a batch of m tokens each picks k experts, gives (mk) assignments in total, to spread load evenly across n experts each expert should process $q=mk/n$ tokens.
Each token finds the cutoff threshold as the (k+1)-th highest biased router score and uses it to calculate the bias update needed to balance load for each expert. For each expert, QB sorts the margins between its router score and every token’s cutoff. It sets negative bias to q+1 the largest margin, leaving exactly q margin above the threshold. Since q/m=k/n, this is (1-k/n) quantile of the margin, which is why it’s called Quantile Balancing.
We are actively tracking Kimi K3’s inference performance on InferenceX.
As of 30th July, all providers on OpenRouter have a floor of $3 per million tokens input and $15 per million tokens output. Both Nvidia and AMD had Day 0 recipes on vLLM, boasting DRAM offload and DSpark speculative decoding.
On InferenceX, we benchmark Kimi K3 serving performance directly on recorded internal claude code traces. We replay an hour of these traces as they reach a steady state. There is a median of 142k input tokens and a median of 444 output tokens per turn with a median of 65 turns per session. The short output tokens per turn is typical for workloads on agentic harnesses, where the agent calls tools frequently, even edits are tool uses.
This benchmark is a big step up from our previous 8k1k/1k1k benchmark, as it truly reflects real-world agentic use cases. From a systems perspective, it is also realistic and closest to production systems. It can reflect KV cache behavior, including prefix cache and KV offloading to DRAM.
For Kimi K3, Day 0 bringup was easier than DSv4 due to better documentation and preparation ahead of weights release. Appropriate images and a speculative decoder model were released at the same time as the weights.

The release of DeepSeek v4 marks another step forward for the open model community - unsurprisingly, it is the product of a Chinese lab. The evolution of its performance over time is of paramount importance to the AI Ecosystem. The open-source InferenceX engineering team has pulled multiple all-nighters to measure performance results for this model on Day 0, Day 1, Day 2, and beyond and bring these results to the world.
Read full storyFor Nvidia, bringup was simple. But due to the models’ sheer size, it doesn’t fit on a single B200 node. We had to use PP to get it working. DSpark also didn’t work with PP.
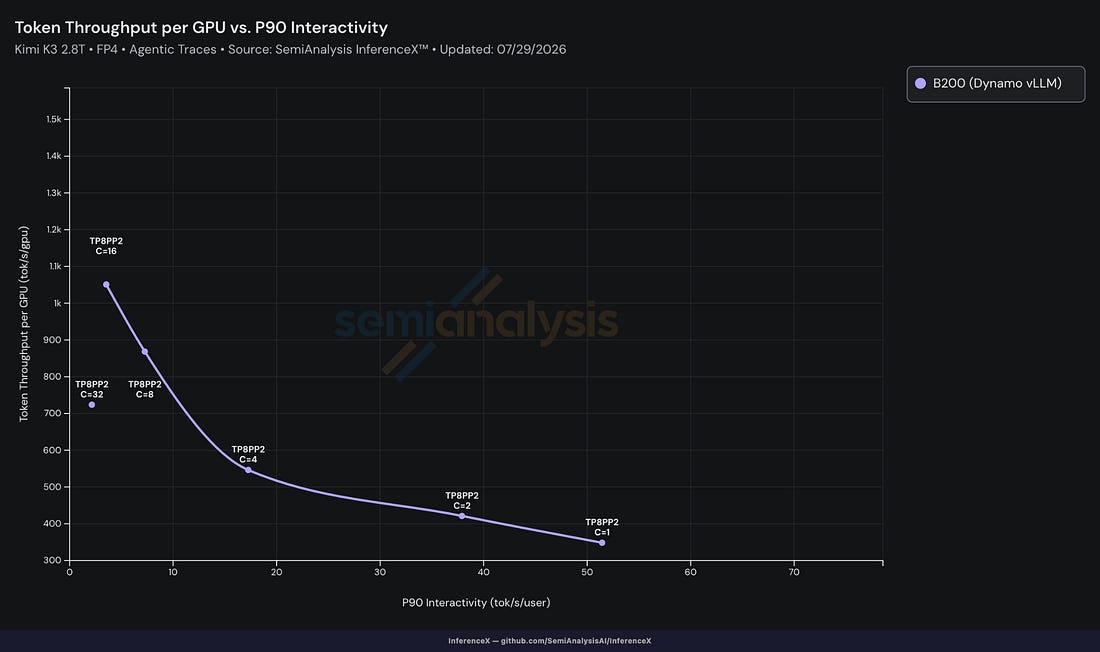
For B300, the model fits on 1 node and serves well. After accounting for the weights, GPU HBM can only hold 3.25M tok. In the graph below, throughput goes up as batch sizes increase until concurrency increases above 8. This roughly correlates to the 3.25M tok KV cache budget, and cache starts to thrash, resulting in hit rates falling to < 10% when theoretical hit rate is 95%...