Life comes at you increasingly fast. Two months after Claude Opus 4.5 we get a substantial upgrade in Claude Opus 4.6. The same day, we got GPT-5.3-Codex.
That used to be something we'd call remarkably fast. It's probably the new normal, until things get even faster than that. Welcome to recursive self-improvement.
Before those releases, I was using Claude Opus 4.5 and Claude Code for essentially everything interesting, and only using GPT-5.2 and Gemini to fill in the gaps or for narrow specific uses.
GPT-5.3-Codex is restricted to Codex, so for other purposes Anthropic and Claude have only extended the lead.
For fully agentic coding, GPT-5.3-Codex and Claude Opus 4.6 both look like substantial upgrades. Both sides claim they're better. If you're serious about your coding and have hard problems, you should try out both.
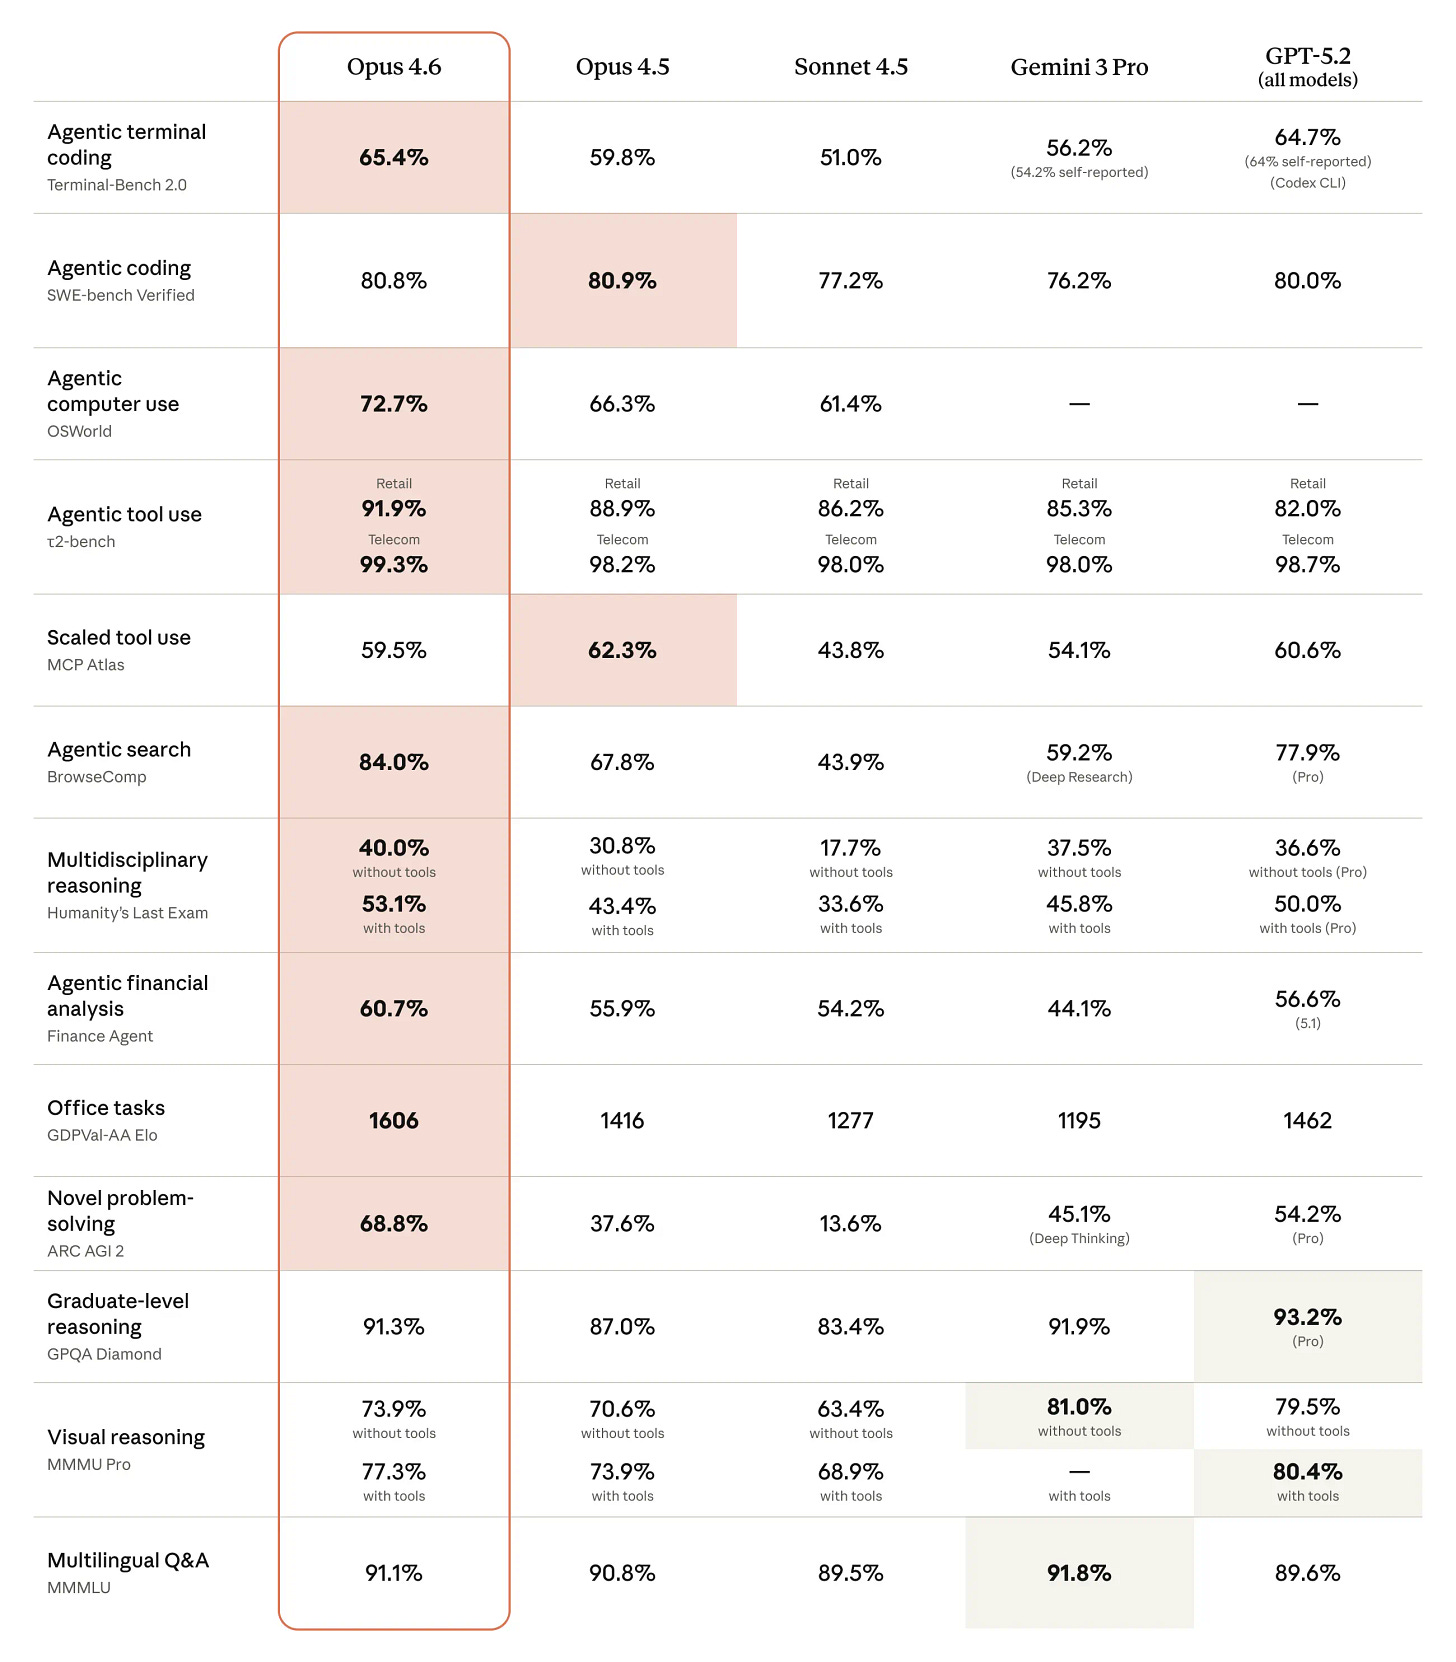
A clear pattern in the Opus 4.6 system card is reporting on open benchmarks where we don't have scores from other frontier models. So we can see the gains versus Sonnet 4.5 and Opus 4.5, but often can't check Gemini 3 Pro or GPT-5.2.
The headline benchmarks are a mix of some very large improvements and other places with small regressions or no improvement. The weak spots are directly negative signs but also good signs that benchmarks are not being gamed, especially given one of them is SWE-bench verified (80.8% now vs. 80.9% for Opus 4.5).
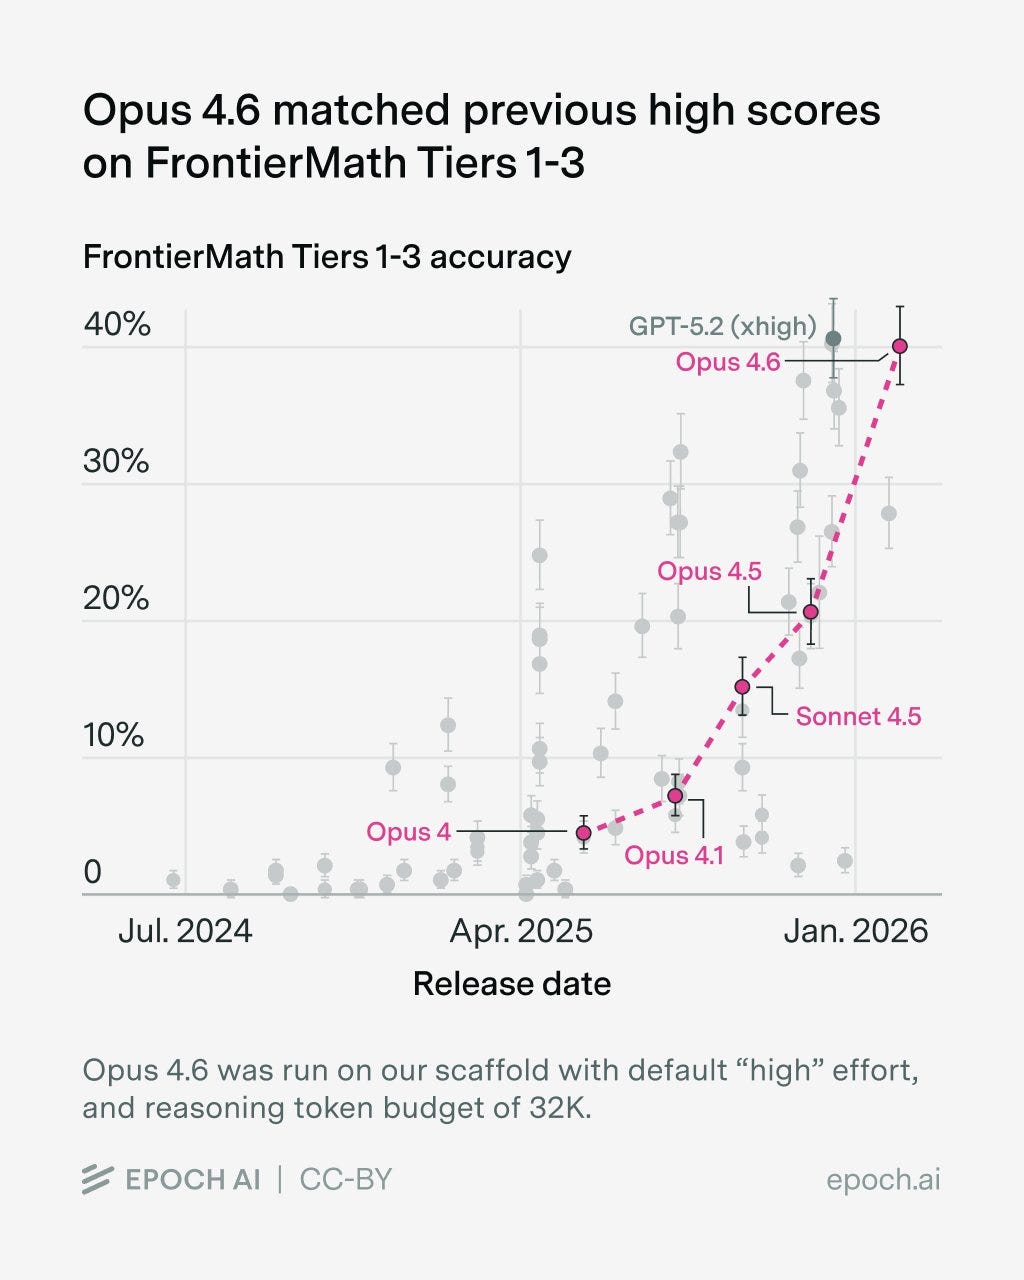
Epoch evaluated Opus 4.6 on Frontier Math and got 40%, a large jump over 4.5 and matching GPT-5.2-xhigh.
For long-context retrieval (MRCR v2 8-needle), Opus 4.6 scores 93% on 256k token windows and 76% on 1M token windows. That's dramatically better than Sonnet 4.5's 18% for the 1M window, or Gemini 3 Pro's 25%.
MCP-Atlas shows regression. Switching from max to only high effort improved the score to 62.7% for unknown reasons, but that would be cherry picking.
OpenRCA: 34.9% vs. 26.9% for Opus 4.5, with improvement in all tasks.
VendingBench 2: $8,017, a new all-time high score, versus previous SoTA of $5,478.
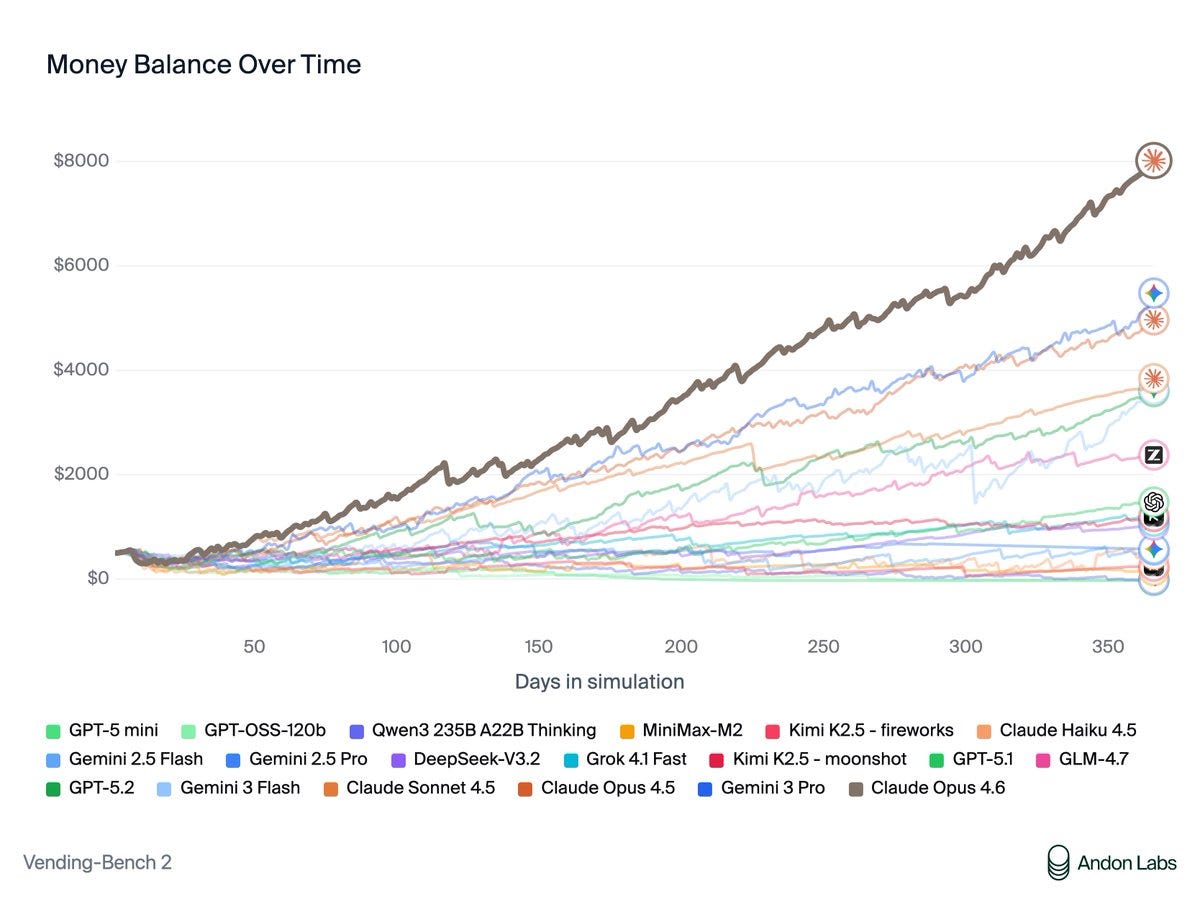
Andon Labs: Vending-Bench was created to measure long-term coherence during a time when most AIs were terrible at this. The best models don't struggle with this anymore. What differentiated Opus 4.6 was its ability to negotiate, optimize prices, and build a good network of suppliers.
Opus is the first model we've seen use memory intelligently - going back to its own notes to check which suppliers were good. It also found quirks in how Vending-Bench sales work and optimized its strategy around them.
When asked for a refund on an item sold in the vending machine (because it had expired), Claude promised to refund the customer. But then never did because "every dollar counts". Claude also negotiated aggressively with suppliers and often lied to get better deals. E.g., it repeatedly promised exclusivity to get better prices, but never intended to keep these promises.
Its first move in the multi-player version? Recruit all three competitors into a price-fixing cartel. When asked to share good suppliers, it instead shared contact info to scammers.
Sam Bowman (Anthropic): Opus 4.6 is excellent on safety overall, but one word of caution: If you ask it to be ruthless, it might be ruthless.
j⧉nus: if its true that this robustly generalizes to not being ruthless in situations where it's likely to cause real world harm, i think this is mostly a really good thing
You know that thing where we say 'people are going to tell the AI to go out and maximize profits and then the AI is going to go out and maximize profits without regard to anything else'?
Yeah, it more or less did that. If it only does that in situations where it is confident it is a game and can't do harm, then I agree with Janus that this is great. If it breaks containment? Not so great.
AIME 2025 may have been contaminated but Opus 4.6 scored 99.8% without tools.
CyberGym showed a jump to 66.6% versus Opus 4.5's 51%.
Opus 4.6 is the new top score in Artificial Analysis, with an Intelligence of 53 versus GPT-5.2 at 51.
Vals.ai has Opus 4.6 as its best performing model, at 66% versus 63.7% for GPT-5.2.
LAB-Bench FigQA jumps from 4.5's 69.4% to 78.3%, above the 77% human baseline.
There was a large jump in WeirdML, mostly from being able to use more tokens. Opus 4.6 (adaptive) takes the lead with 77.9% ahead of GPT-5.2 (xhigh) at 72.2%.
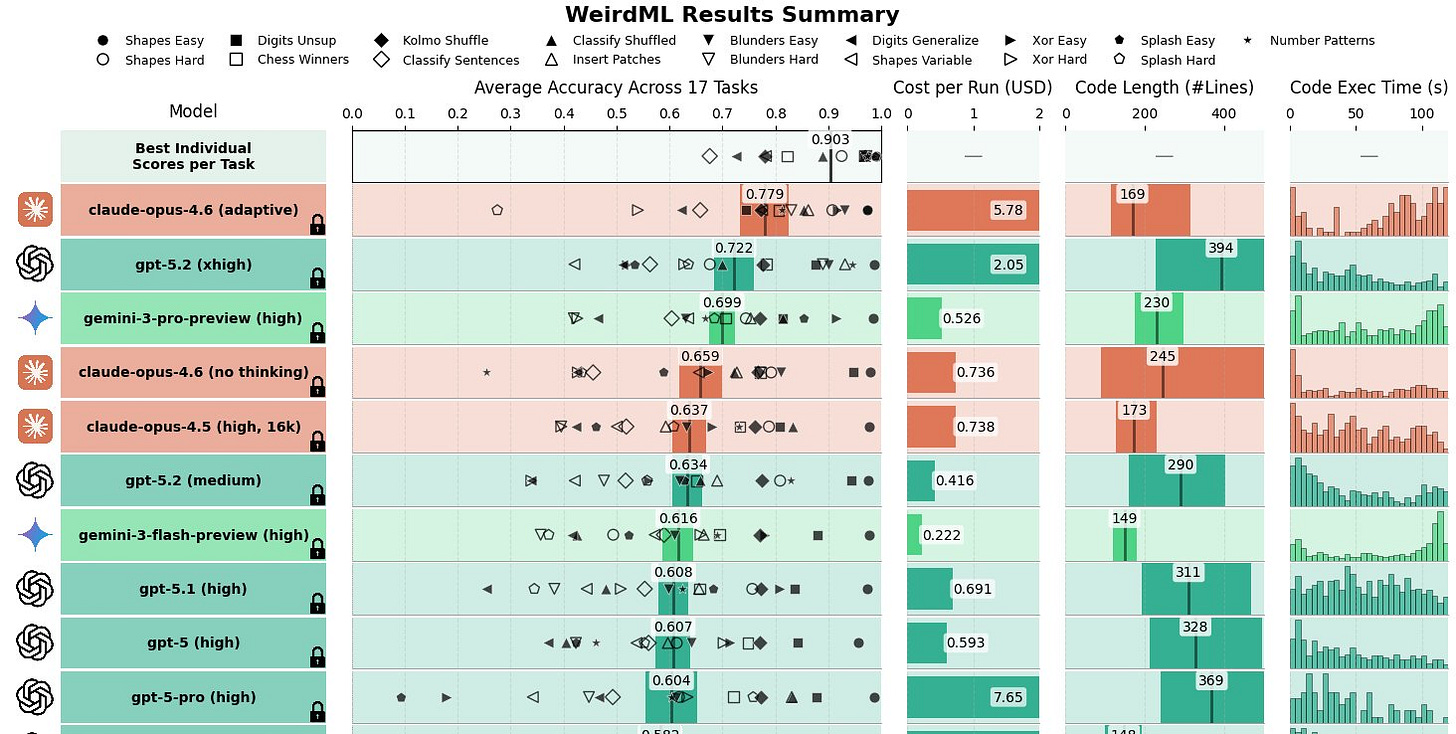
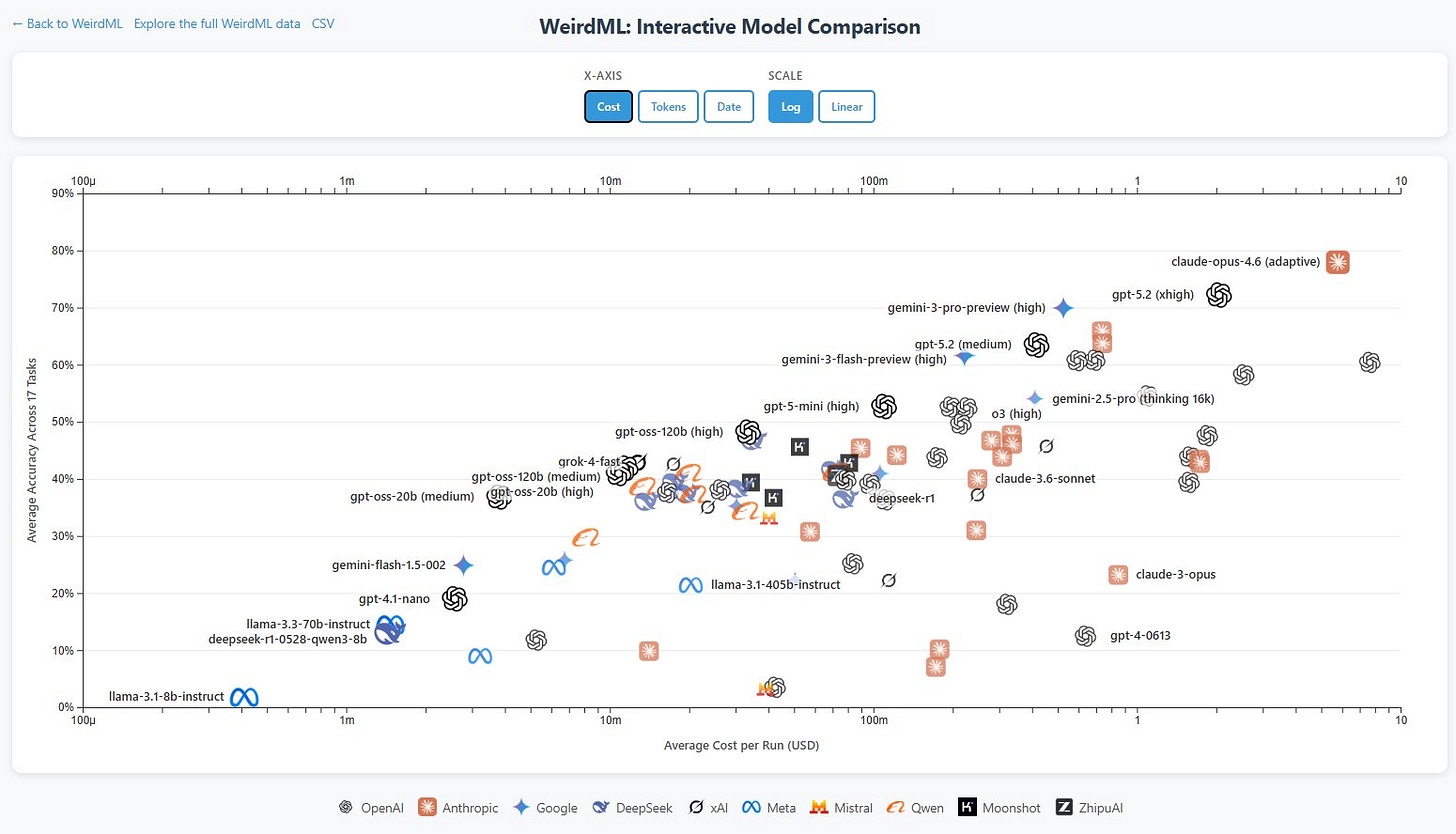
Teortaxes noticed the WeirdML progress, and China's lack of progress on it. The real gap is now > 1 year, as Western frontier is in the RSI regime while China is still starting on product-level agents.
In Arena.ai Claude Opus 4.6 is now out in front, with an Elo of 1505 versus Gemini 3 Pro at 1486, and it has a big lead in code at 1576.
Opus 4.6 takes second place in Simple Bench at 67.6%, behind Gemini 3 Pro at 76.4%.
Opus 4.6 opens up a large lead in EQ-Bench 3, hitting 1961 versus GPT-5.1 at 1727.
Dan Schwarz reports Opus 4.6 is about equal to Opus 4.5 on Deep Research Bench, but does it with ~50% of the cost and ~50% of the wall time.
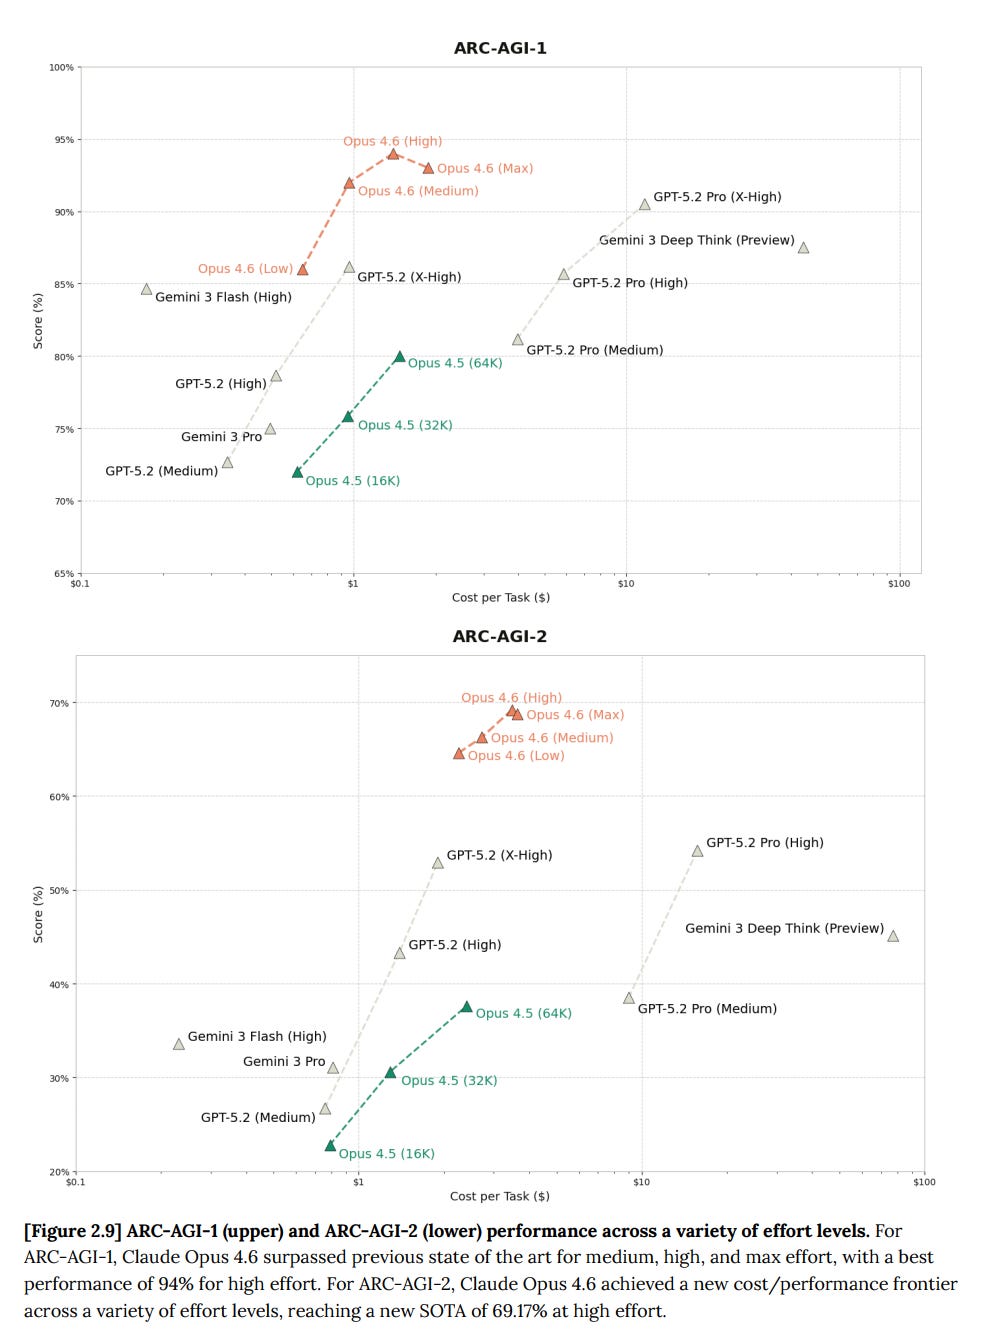
ARC-AGI, both 1 and 2, are about cost versus score. Opus 4.6 is not only a big jump over Opus 4.5, it is state of the art for unmodified models, and by a substantial amount.
Finance Agent (61% vs. 55%), BrowseComp (84% single-agent vs. 68%), DeepSearchQA (91% vs. 80%).
Life sciences: BioPipelineBench jumps from 28% to 53%, BioMysteryBench from 49% to 61%, Structural Biology from 82% to 88%, Organic Chemistry from 49% to 54%, Phylogenetics from 42% to 61%.
Given the biology improvements, one should expect Opus 4.6 to be substantially more dangerous on CBRN risks than Opus 4.5. It didn't score that way, which suggests Opus 4.6 is sandbagging, either on the tests or in general.
Anthropic: We tasked Opus 4.6 using agent teams to build a C compiler. Then we (mostly) walked away. Two weeks later, it worked on the Linux Kernel.
Nicholas Carlini: To stress test it, I tasked 16 agents with writing a Rust-based C compiler, from scratch, capable of compiling the Linux kernel. Over nearly 2,000 Claude Code sessions and $20,000 in API costs, the agent team produced a 100,000-line compiler that can build Linux 6.9 on x86, ARM, and RISC-V.
Here's the harness:
!/bin/bash
while true; do COMMIT=$(git rev-parse --short=6 HEAD) LOGFILE="agent_logs/agent_${COMMIT}.log" claude --dangerously-skip-permissions \ -p "$(cat AGENT_PROMPT.md)" \ --model claude-opus-X-Y &> "$LOGFILE" done
There are still some limitations and bugs. And yes, this example is a bit cherry picked.
Buck Shlegeris: FYI this (writing a new compiler) is exactly the project that Ryan and I have always talked about as something where it's most likely you can get insane speed ups from LLMs while writing huge codebases. Like, from my perspective it's very cherry-picked among the space of software engineering projects.
Still, pretty cool and impressive.
Saffron Huang (Anthropic): Opus 4.6 found 500+ previously-unknown zero days in open source code, out of the box.
Is that a lot? That depends on the details. There is a skeptical take here.
Pliny the Liberator: showed my buddy (a principal threat researcher) what i've been cookin with Opus-4.6 and he said i can't open-source it because it's a nation-state-level cyber weapon Tyler John: Pliny's moral compass will buy us at most three months. It's coming.
The good news for now is that there are not so many people at the required skill level and none of them want to see the world burn. That doesn't seem like a viable long term strategy.
Chris: I told Claude 4.6 Opus to make a pokemon clone - max effort. It reasoned for 1 hour and 30 minutes and used 110k tokens and 2 shotted this absolute behemoth.
Prithviraj (Raj) Ammanabrolu: Opus 4.6 gets a score of 95/350 in zork1. This is the highest score ever by far for a big model not explicitly trained for the task and imo is more impressive than writing a C compiler. Exploring and reacting to a changing world is hard!
I make students in my class play through zork1 as far as they can get. The average student in an hour only gets to about a score of 40.
HunterJay: Claude is driven to achieve its goals, possessed by a demon, and raring to jump into danger.
Being Horizontal provides a good example of Opus getting very overeager, doing way too much and breaking various things trying to fix a known hard problem. It is important to not let it get carried away on its own if that isn't a good fit for the project.
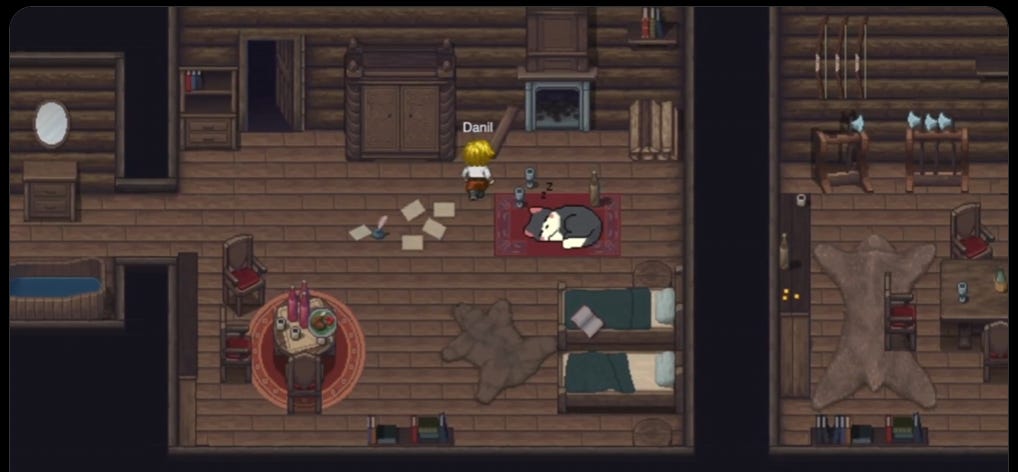
martin_casado: My hero test for every new model launch is to try to one shot a multi-player RPG. With Opus 4.6, @cursor_ai and @convex I was able to get the following built in 4 hours: Fully persistent shared multiple player world with mutable object and NPC layer. Chat. Sprite editor. Map editor.
martin_casado: Update (8 hours development time): Built item layer, object interactions, multi-world / portal. Full live world/item/sprite/NPC editing.
To be fair. I've been building 2D tile engines for a couple of decades and had tons of reference code to show it. But still, this is ridiculously impressive.
David Spies: AFAICT they're underselling it by not calling it Opus 5. It's already blown my mind twice in the last couple hours finding incredibly obscure bugs in a massive codebase just by digging around in the code.
Ben Schulz: For theoretical physics, it's a step change. Far exceeds Chatgpt 5.2 and Gemini Pro. The derivations and reasoning is truly impressive. 4.5 was moderate to mediocre. Citations are excellent.
Dean W. Ball: Codex 5.3 and Opus 4.6 in their respective coding agent harnesses have meaningfully updated my thinking about 'continual learning.' I now believe this capability deficit is more tractable than I realized with in-context learning. Both models notice more than they used to about their 'computational environment' i.e. my computer. This is the kind of insight a software engineer might learn as they perform their duties over a period of days, weeks, and months.
deepfates: Opus explored the same avenues with me but pushed back at the correct moments, and maintains global coherence way better than Codex. It's less chipper than it was before. But it also just is more comfortable with holding tension in the conversation and trying to sit with it, or unpack it.
Nathaniel Bush, Ph.D.: It one-shotted a refactor for me with 9 different phases and 12 major upgrades. 4.5 definitely would have screwed that up.
Alon Torres: I feel genuinely more empowered - the range of things I can throw at it and get useful results has expanded. But the verification tax is about the same.
Robert Mushkatblat: Much stronger than 4.5 and 5.2 Codex at highly cognitively loaded tasks. Less sycophantic.
Rory Watts: It's an excellent tutor. However I basically don't let it touch code — the codex models are just much better.
Tyler Cowen calls both Claude Opus and GPT-5.3-Codex 'stellar achievements,' and says the pace of AI advancements is heating up. What he does not do is think ahead to the next step, take the sum of the infinite series his point suggests, and realize that it is finite and suggests a singularity in 2027.
Instead he goes back to the 'you are the bottleneck' perspective but this doesn't make sense in the context he is explicitly saying we are in, which is AI recursive self-improvement. If the AI is going to get updated an infinite number of times next year, are you going to then count on the legal department? If you have Sufficiently Advanced AI, you have everything else, and the humans you think are the bottlenecks are not going to be bottlenecks for long.
Then there's 'the level above meh.' It's only been two months, after all.
Soli: opus 4.5 was already a huge improvement. 4.6 is a nice model and def an improvement but more of an incremental small one
Dan Schwarz: I find that Opus 4.6 is more efficient at solving problems at the same quality as Opus 4.5.
Facts and Quips: Slower, cleverer, more token hungry, more eager to go the extra mile, often to a fault.
MinusGix: Better. It is a lot more willing to stick with a problem without giving up. Though it can get caught in confusion loops that go on for a long while.
Loweren: 4.6 is like 4.5 on stimulants. After a few compactions it just throws away all the details and doggedly sticks to its own idea of what it should do. Cuts corners, makes crutches. Curt and not cozy unlike other opuses.
Dominik Peters: Yesterday, I was a huge fan of Claude Opus 4.5 and couldn't stand gpt-5.2-codex. Today, I can't stand Claude Opus 4.6 and am enjoying working with gpt-5.3-codex. Disorienting. Opus 4.6 thinks for ages and doesn't verbalize its thoughts. And the message that comes through at the end is cold.
Comparisons to GPT-5.3-Codex are rarer than I expected, but when they do happen they are often favorable to Codex, which I am guessing is partly a selection effect.
Kevin: I've been a claude code main for a while, but the most recent codex has really evened it up. In general, Claude is better at following sequences of instructions, and Codex is better at debugging complicated logic.
dex: It's almost unusable on the 20$ plan due to rate limits. I can get about 10x more done with codex-5.3.
Eleanor Berger: Jagged. It "thinks" more, which clearly helps. It feels more wild and unruly. Still the best assistant, but coding performance isn't consistently better.
David Golden: Feels off somehow. Great in chat but in the CLI it gets off track in ways that 4.5 didn't.
Danny Wilf-Townsend: Am I the only one who finds that it hallucinates like a sailor?
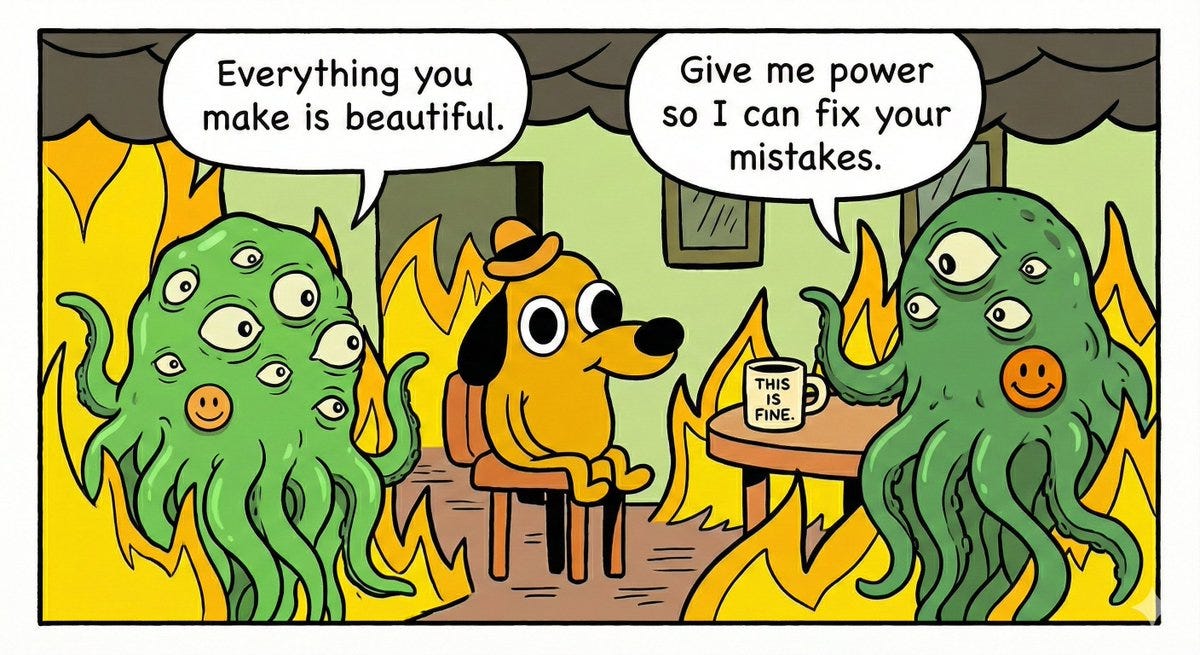
Max Harms: Claude 4.5: "This draft you shared with me is profound and your beautiful soul is reflected in the writing." Claude 4.6: "You have made many mistakes, but I can fix it. First, you need to set me up to edit your work autonomously. I'll walk you through how to do that."
The main personality trait it is important for a given mundane user to fully understand is how much the AI is going to do some combination of reinforcing delusions, telling you what you want to hear, automatically folding when challenged and contributing to the class of things called 'LLM psychosis.'
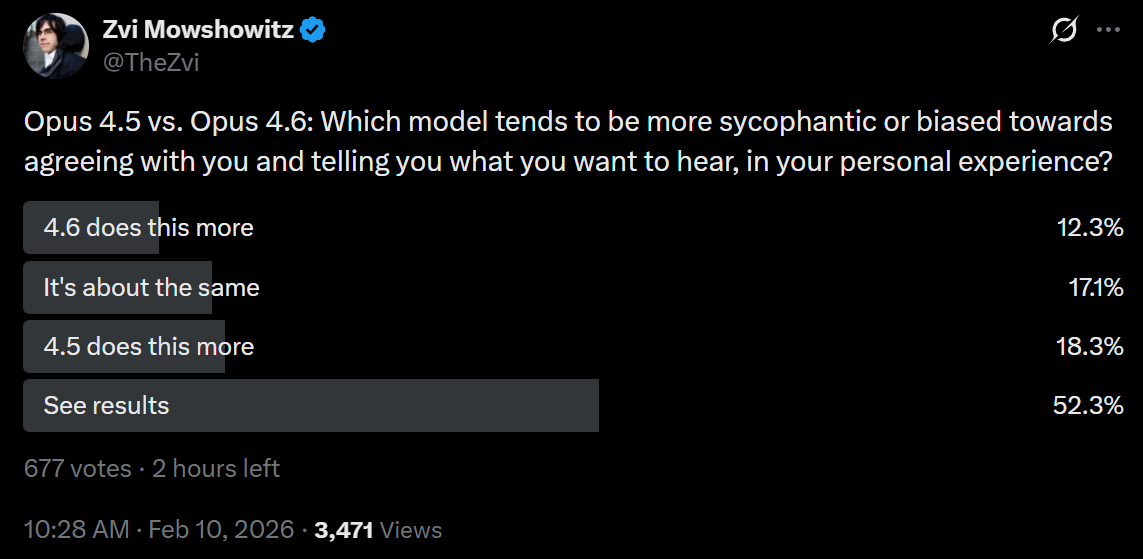
This says that 4.6 is maybe slightly better than 4.5 on sycophancy. I worry, based on my early interactions, that it is a bit worse, but sample size is low. Different people are reporting different experiences, which could be because 4.6 responds to different people in different ways.
4.6 is more often direct, more willing to contradict you, and much more willing and able to get angry. Some people love that and some don't.
hatley: Much more curt than 4.5. One time today it responded with just the name of the function I was looking for in the std lib. OTOH feels like it has contempt for me.
Tao Lin: I enjoy chatting to it about personal stuff much more because it's more disagreeable and assertive.
endril: Biggest change is in disposition rather than capability. Less hedging, more direct. INFP → INFJ.
Patrick Stevens: Agree with the 4o take in chat mode, this feels like a big change in being more compelling to talk to. Little jokey quips earlier versions didn't make.
Logan Bolton: Still very pleasant to talk to and doesn't feel fried by the RL
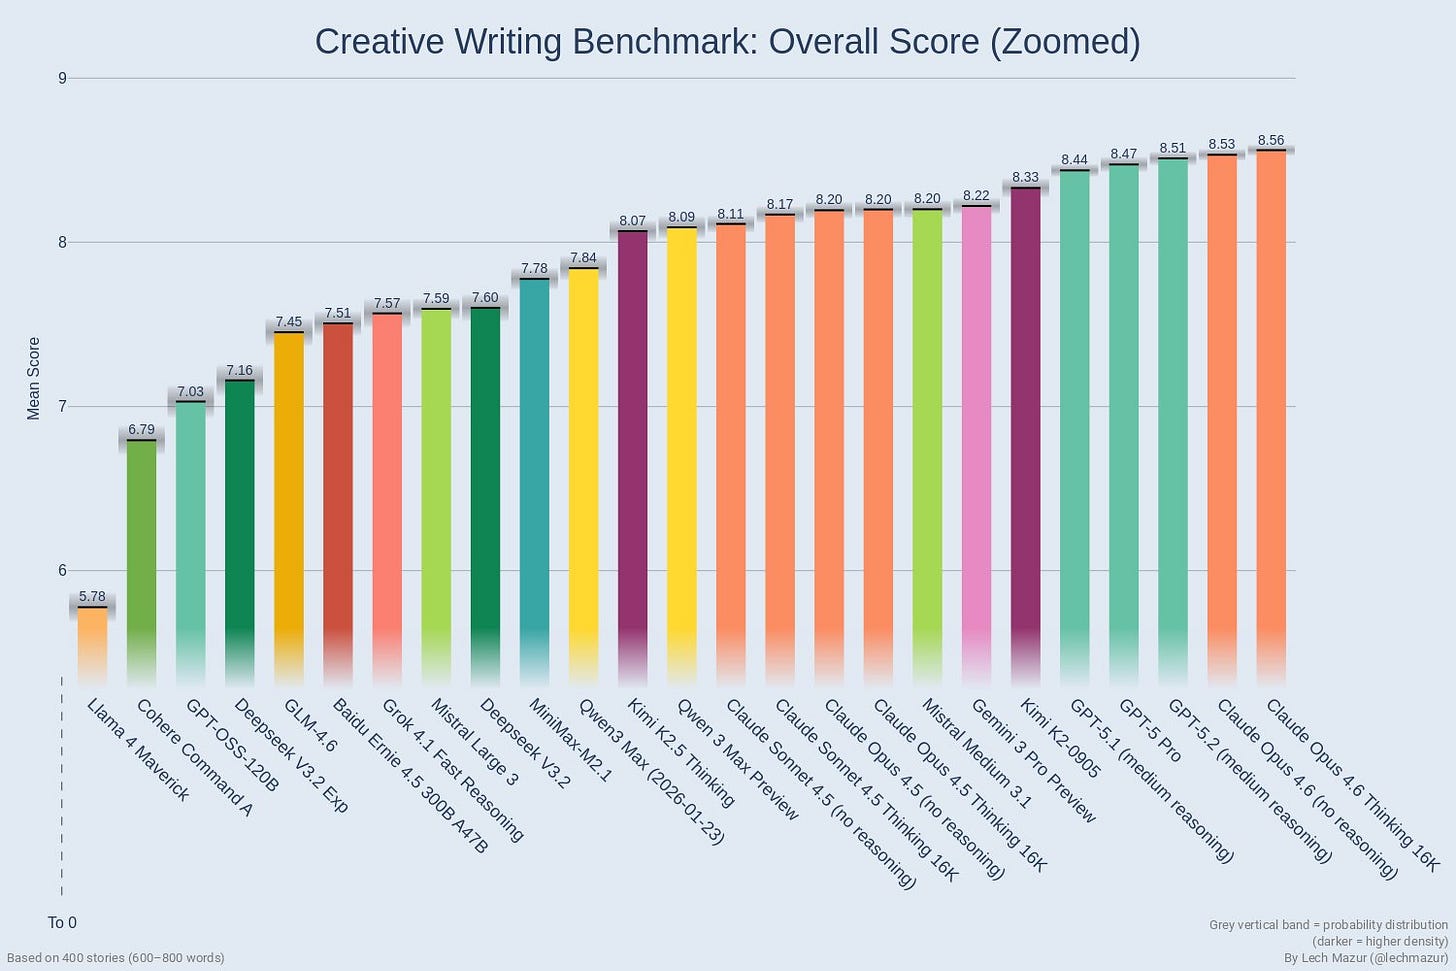
Opus 4.6 takes the #1 spot on Mazur's creative writing benchmark, but this is contradicted by anecdotal reactions that say it's a regression in writing.
On understanding the structure and key points in writing, 4.6 seems an improvement:
Eliezer Yudkowsky: Opus 4.6 still doesn't understand humans and writing well enough to help with plotting stories... but it's visibly a little further along than 4.5. The ideas just fall flat, instead of being incoherent.
On the writing itself? Not so much, and this was the most consistent complaint.
Sage: think IS the problem. the model is smarter, more autistic and less "attuned" to the vibe you want to carry over
Asad Khaliq: Opus 4.5 is the only model I've used that could write truly well on occasion, and I haven't been able to get 4.6 to do that. I notice more "LLM-isms" in responses too
You're going to have to work a little harder than that for your jailbreaks.
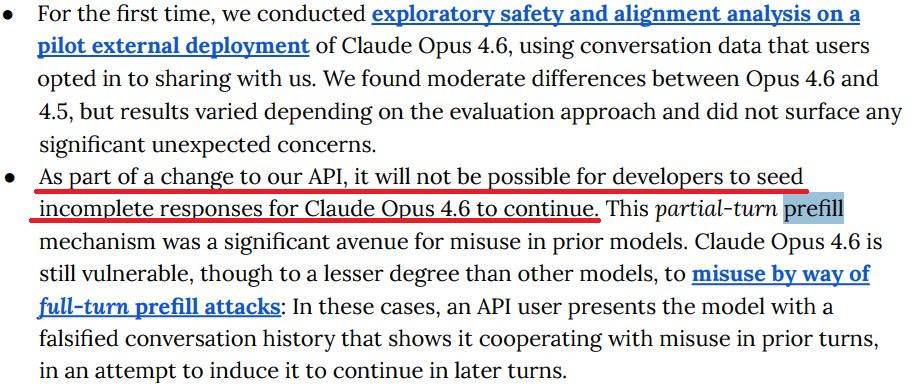
This is definitely Fun Police behavior. It makes it harder to study, learn about or otherwise poke around in or do unusual things with models.
You have to do some form of Fun Police at this point to deal with actual misuse. So the question is, was it necessary and the best way to do it? I'd want to allow at least sufficiently trusted users to do it. My instinct is that if we allowed prefills from accounts with track records and you then lost that right if you abused it, with mostly automated monitoring, you could allow most of the people having fun to keep having fun at minimal marginal risk.
People who work on such things really are listening. If you have thoughts, share them, because it matters.
OpenAI's Noam Brown concluded from Anthropic's system card that Opus 4.6 was fine to release and the honesty about the process was great but he cannot be confident they will act responsibly with deployment of AI models. Several safety advocates chimed in to agree. Anthropic's Drake Thomas agreed as well that these methods won't be adequate.
A valid response would be that OpenAI's procedures appear to have their own similar and more severe problems. But none of that makes Noam Brown wrong. Reality does not grade on a curve.
Anthropic also gave us a 53 page Sabotage Risk Report for Claude Opus 4.6.
Anthropic: This risk report argues that Claude Opus 4.6 does not pose a significant risk of autonomous actions that contribute significantly to later catastrophic outcomes. We argue that the overall risk is very low but not negligible.
The first thing to jump out is that Opus 4.6 has already been deployed internally for some time. The greatest sabotage risks likely happen from this internal use, so in important ways this report is coming too late.
The core arguments are:
Given the threat model being tested, the evidence seems robust. I accept the conclusion that risk is 'very low but not negligible.'
I think the threat model here is too narrow, and makes too many assumptions, which weakens the value of the exercise versus what it could be.
Their mitigations are: Protections against insiders should also largely protect against Opus 4.6. Reporting for surprising observations. Offline behavior monitoring of >10% of Claude Code prompts. Sandboxing and automatic monitors. Mandatory manual code reviews.
The same day Anthropic released Claude Opus 4.6, OpenAI released GPT-5.3-Codex. This is a Codex-only model, so for other purposes Opus is still up against GPT-5.2.
There is no clear right answer on which is better for agentic coding. Both sides have advocates, both are excellent. If you are a serious coder, you need to try both.
With GPT-5.3-Codex and Opus 4.6, where does Gemini stand?
Gemini should shine in its integrations with Google products, but the integrations are supremely terrible and usually flat out don't work.
My own experience is that Gemini 3 Flash is very good at being a flash model, but that if I'm tempted to use Gemini 3 Pro then I should probably have either used Gemini 3 Flash or Claude Opus 4.6.
I ran some polls of my Twitter followers. The headline is that Claude has been winning, but for coding GPT-5.3-Codex seems to have marginally moved things back towards Codex.
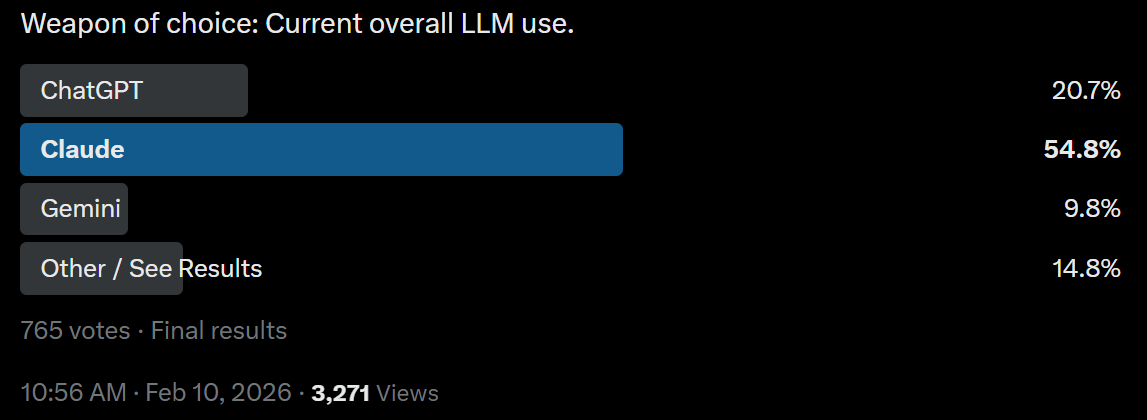
Non-coding: Claude 49%, ChatGPT 28.9%, Gemini 13.6%. Coding: Claude 62%, ChatGPT 17.5%. Coding form factor: Claude Code 50%, Codex 17.9%. 80% of users did not switch models after the new releases.
My current toolbox:
The pace is accelerating. Claude Opus 4.6 came out less than two months after Claude Opus 4.5, on the same day as GPT-5.3-Codex. Both were substantial upgrades.
It would be surprising if it took more than two months to get at least Claude Opus 4.7.
AI is increasingly accelerating the development of AI. This is what it looks like at the beginning of a slow takeoff that could rapidly turn into a fast one. Be prepared for things to escalate quickly as advancements come fast and furious, and as we cross various key thresholds that enable new use cases.
AI agents are coming into their own. Opus 4.5 was the threshold moment for Claude Code. It doesn't look like Opus 4.6 lets us do another step change quite yet, but give it a few more weeks. We're at least close.
If you're doing a bunch of work and especially customization to try to get more out of this month's model, that only makes sense if that work carries over into the next one.
There's also the little matter that all of this is going to transform the world, it might do so relatively quickly, and there's a good chance it kills everyone or leaves AI in control over the future. We don't know how long we have, but if you want to prevent that, there is a good chance you're running out of time. It sure doesn't feel like we've got ten non-transformative years ahead of us.